NumPy sum(): Array Totals, Axes and Missing Values
np.sum() adds array elements. With no axis, it returns a total across the entire array. Choose an axis for row or column totals, select values with a Boolean mask, and check dtype and missing data before interpreting the result.
| Option | Purpose |
|---|---|
| a | Input array or array-like values |
| axis | None for all elements, an integer for one axis, or a tuple for several |
| dtype | Accumulator and result type |
| out | Destination array matching the result shape |
| keepdims | Retain reduced axes as dimensions of size one |
| where | Boolean selection mask, broadcastable to the input |
| initial | Starting value added to each reduced result |
Create the Sample Array
Rows and columns are positions until you assign them a meaning. This fixed 3-by-3 sample makes the totals easy to verify. You can also generate practice arrays with a random Generator.
import numpy as np

def sample_array():
    return np.array([[6, 3, 2], [2, 6, 2], [6, 2, 3]])

my_data = sample_array()
print(my_data)
print("Shape:", my_data.shape)
assert my_data.shape == (3, 3)
Expected output
[[6 3 2]
 [2 6 2]
 [6 2 3]]
Shape: (3, 3)
Total, Column Totals and Row Totals
Unlike Pandas DataFrame.sum, NumPy sum defaults to axis=None, which reduces all elements to one total. axis=0 reduces down the rows, leaving a total for each column. axis=1 reduces across columns, leaving a total for each row. See axis reduction for more shape examples.
my_data = sample_array()
print("All elements:", np.sum(my_data))
print("Column totals:", my_data.sum(axis=0))
print("Row totals:", my_data.sum(axis=1))
assert my_data.sum() == 32
np.testing.assert_array_equal(my_data.sum(axis=0), [14, 11, 7])
np.testing.assert_array_equal(my_data.sum(axis=1), [11, 10, 11])
Expected output
All elements: 32
Column totals: [14 11  7]
Row totals: [11 10 11]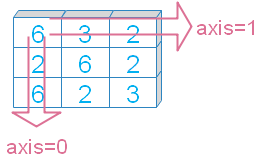
Choose the Accumulator dtype
dtype controls the accumulator and result type. Small integer inputs can be promoted automatically, so the default result does not always have the input dtype. Explicit narrow integer accumulators can overflow. These small sample totals fit every demonstrated type. See NumPy data types.
my_data = sample_array()
for dtype in [np.int8, np.int32, np.float64, np.complex128]:
    result = my_data.sum(axis=1, dtype=dtype)
    print(dtype.__name__, result)
    np.testing.assert_array_equal(result, [11, 10, 11])
Expected output
int8 [11 10 11]
int32 [11 10 11]
float64 [11. 10. 11.]
complex128 [11.+0.j 10.+0.j 11.+0.j]
Check Integer Overflow before Interpreting Totals
NumPy integer arithmetic wraps on overflow without raising an exception. A wider accumulator can avoid this for a bounded dataset, but int64 is also finite. Validate a realistic upper bound rather than assuming any integer dtype is unlimited.
values = np.array([100, 100], dtype=np.int8)
print("Default promoted accumulator:", values.sum())
print("Explicit int8 accumulator:", values.sum(dtype=np.int8))
print("Explicit int64 accumulator:", values.sum(dtype=np.int64))
assert values.sum(dtype=np.int8) == -56
assert values.sum(dtype=np.int64) == 200
Expected output
Default promoted accumulator: 200
Explicit int8 accumulator: -56
Explicit int64 accumulator: 200
keepdims Retains Reduced Axes as Size One
keepdims=True retains the number of dimensions, but the reduced axes become length one. It does not keep the original shape. A row total shaped (3, 1) broadcasts back across a (3, 3) array, which is useful for calculating within-row shares.
my_data = sample_array()
print("All axes retained:", my_data.sum(keepdims=True))
print("Scalar:", my_data.sum(keepdims=False))
row_totals = my_data.sum(axis=1, keepdims=True)
print("Row-total shape:", row_totals.shape)
assert row_totals.shape == (3, 1)
shares = my_data / row_totals
print("Within-row shares:")
print(shares.round(3))
np.testing.assert_allclose(shares.sum(axis=1), np.ones(3))
Expected output
All axes retained: [[32]]
Scalar: 32
Row-total shape: (3, 1)
Within-row shares:
[[0.545 0.273 0.182]
 [0.2   0.6   0.2  ]
 [0.545 0.182 0.273]]
out: Write Totals into a Compatible Array
out must match the result shape, not necessarily the input shape. The returned object is the supplied output array. Choose a dtype that can represent the totals: casting into a narrow destination can lose information.
my_data = sample_array()
column_output = np.zeros(3, dtype=np.int64)
result = np.sum(my_data, axis=0, out=column_output)
print("Column output:", column_output)
assert result is column_output
np.testing.assert_array_equal(column_output, [14, 11, 7])
scalar_output = np.array(0, dtype=np.int64)
np.sum(my_data, out=scalar_output)
print("Scalar output:", scalar_output)
assert scalar_output.shape == () and scalar_output == 32
Expected output
Column output: [14 11  7]
Scalar output: 32
where: Include Selected Columns
A Boolean mask of shape (3,) broadcasts across each row of this array. True includes a value, False excludes it. This mask selects the first and third columns; it does not select rows. Use Boolean masks to express the selection deliberately.
my_data = sample_array()
mask = np.array([True, False, True])
print("Selected total:", my_data.sum(where=mask))
print("Selected row totals:", my_data.sum(axis=1, where=mask))
print("Selected column totals:", my_data.sum(axis=0, where=mask))
assert my_data.sum(where=mask) == 21
np.testing.assert_array_equal(my_data.sum(axis=1, where=mask), [8, 4, 9])
np.testing.assert_array_equal(my_data.sum(axis=0, where=mask), [14, 0, 7])
Expected output
Selected total: 21
Selected row totals: [8 4 9]
Selected column totals: [14  0  7]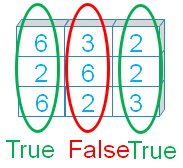
Condition Masks and Row Selection
A condition can create a full elementwise mask. To select rows with a broadcast mask, add a size-one column dimension. Compare with np.where(), which performs conditional selection rather than returning a reduction.
my_data = sample_array()
print("Values at least 5:", my_data.sum(where=my_data >= 5))
row_mask = np.array([True, False, True])[:, None]
print("First and third rows:", my_data.sum(where=row_mask))
assert my_data.sum(where=my_data >= 5) == 18
assert my_data.sum(where=row_mask) == 22
Expected output
Values at least 5: 18
First and third rows: 22
initial Is Added to Each Reduced Result
initial is a starting value for each reduction. With axis=1, it is added to every row total, not once to the entire dataset. Include it only when it represents the quantity you intend to add.
my_data = sample_array()
print("Grand total plus 10:", my_data.sum(initial=10))
print("Each row plus 10:", my_data.sum(axis=1, initial=10))
assert my_data.sum(initial=10) == 42
np.testing.assert_array_equal(my_data.sum(axis=1, initial=10), [21, 20, 21])
Expected output
Grand total plus 10: 42
Each row plus 10: [21 20 21]
Reduce Several Axes in a Three-Dimensional Array
A tuple reduces several axes together. Here dimensions represent two stores, three days and two products. Reducing the day and product axes leaves one total per store. axis=-1 selects the last axis.
data = np.arange(1, 13).reshape(2, 3, 2)
print("Input shape:", data.shape)
print("Store totals:", data.sum(axis=(1, 2)))
print("Daily totals within each store:")
print(data.sum(axis=-1))
np.testing.assert_array_equal(data.sum(axis=(1, 2)), [21, 57])
assert data.sum(axis=(1, 2), keepdims=True).shape == (2, 1, 1)
Expected output
Input shape: (2, 3, 2)
Store totals: [21 57]
Daily totals within each store:
[[ 3  7 11]
 [15 19 23]]
NaN: Complete Total versus Known Subtotal
sum propagates a NaN in a numeric reduction. nansum ignores NaN, producing a subtotal of known values. An all-NaN nansum is zero, so report counts when no observations are known. See NaN and data types.
values = np.array([10.0, np.nan, 5.0])
print("sum:", values.sum())
print("Known subtotal:", np.nansum(values))
unknown = np.array([np.nan, np.nan])
print("All-NaN nansum:", np.nansum(unknown))
assert np.isnan(values.sum())
assert np.nansum(values) == 15
assert np.nansum(unknown) == 0
Expected output
sum: nan
Known subtotal: 15.0
All-NaN nansum: 0.0
Empty Selections and Zero Observed Values
The sum of an empty numeric array, or an all-False selection, is zero. That mathematical identity does not prove that measured revenue was zero. Keep a count to distinguish a known zero from no selected observations.
values = np.array([0.0, 12.0])
none_selected = np.array([False, False])
zero_selected = np.array([True, False])
print("Empty sum:", np.array([], dtype=float).sum())
print("No observations:", values.sum(where=none_selected), "count:", none_selected.sum())
print("Known zero:", values.sum(where=zero_selected), "count:", zero_selected.sum())
assert none_selected.sum() == 0 and zero_selected.sum() == 1
Expected output
Empty sum: 0.0
No observations: 0.0 count: 0
Known zero: 0.0 count: 1
Floating-Point Totals and Tolerance Checks
Binary floating-point arithmetic need not produce an exact decimal total. A float64 accumulator can improve precision for many float32 inputs, but it cannot recover precision already lost in source values. Use a tolerance appropriate to the measurement. For exact money arithmetic, consider an integer minor-unit representation with validated bounds.
values = np.array([0.1, 0.2, 0.3], dtype=np.float64)
total = values.sum(dtype=np.float64)
print("Total:", total)
print("Close to 0.6:", np.isclose(total, 0.6, rtol=0, atol=1e-12))
np.testing.assert_allclose(total, 0.6, rtol=0, atol=1e-12)
minor_units = np.array([10, 20, 30], dtype=np.int64)
assert minor_units.sum(dtype=np.int64) == 60
Expected output
Total: 0.6000000000000001
Close to 0.6: True
Practical Sales Matrix: State What Rows and Columns Mean
This synthetic matrix has four days down the rows and Books, Pens and Gifts across columns. Missing values are unknown sales measurements. Day 4 has no known values; zeros on other days are recorded zero sales. Compute known subtotals and valid counts together.
def sales_data():
    return np.array([[120.0, 30.0, 0.0],
                     [80.0, np.nan, 20.0],
                     [100.0, 40.0, 10.0],
                     [np.nan, np.nan, np.nan]])

sales = sales_data()
valid = ~np.isnan(sales)
daily_known = np.sum(sales, axis=1, where=valid, dtype=np.float64)
daily_count = valid.sum(axis=1)
product_known = np.sum(sales, axis=0, where=valid, dtype=np.float64)
print("Daily known subtotals:", daily_known)
print("Known values per day:", daily_count)
print("Books/Pens/Gifts known subtotals:", product_known)
np.testing.assert_array_equal(daily_known, [150, 100, 150, 0])
np.testing.assert_array_equal(daily_count, [3, 2, 3, 0])
np.testing.assert_array_equal(product_known, [300, 70, 30])
Expected output
Daily known subtotals: [150. 100. 150.   0.]
Known values per day: [3 2 3 0]
Books/Pens/Gifts known subtotals: [300.  70.  30.]
Keep Unknown Days Missing and Reconcile Subtotals
Mask a day with no observations to NaN for a report of known daily subtotals. A complete-day total also requires all three product measurements. Reconcile the known grand subtotal through both axes, while disclosing the four missing measurements. Use broadcasting when combining masks and arrays.
sales = sales_data()
valid = ~np.isnan(sales)
known = np.sum(sales, axis=1, where=valid, dtype=np.float64)
count = valid.sum(axis=1)
known_report = np.where(count > 0, known, np.nan)
complete_report = np.where(count == sales.shape[1], known, np.nan)
print("Known daily subtotals:", known_report)
print("Complete daily totals:", complete_report)
print("Known grand subtotal:", np.nansum(sales))
print("Missing measurements:", np.isnan(sales).sum())
assert np.isnan(known_report[3])
assert np.isnan(complete_report[1])
assert np.nansum(sales) == np.nansum(known_report) == np.nansum(sales, axis=0).sum() == 400
assert np.isnan(sales).sum() == 4
Expected output
Known daily subtotals: [150. 100. 150.  nan]
Complete daily totals: [150.  nan 150.  nan]
Known grand subtotal: 400.0
Missing measurements: 4
Common NumPy Sum Problems
Wrong total shape: check axis and keepdims. ID or unrelated field included: select the intended numeric measures before building an array. Unexpected negative integer total: inspect accumulator and output dtypes for overflow. NaN result: decide whether you need a complete total or a known subtotal. Zero with no observations: include valid counts. Mask selects the wrong direction: inspect its shape and broadcasting. initial counted several times: it applies to each reduced result. Decimal comparison fails: use a meaningful tolerance. Contrast totals with mean(), max() and min().
Exercise: Exclude One Product and Keep Unknown Days Missing
Using the sales matrix, include Books and Gifts, exclude Pens and ignore missing measurements. Report one subtotal per day, retaining NaN when neither included product is known. Predict 120, 100, 110 and NaN, with a known grand subtotal of 330.
Exercise Solution
Combine the product-selection mask with the validity mask before summing. Count only included known values when deciding whether a daily subtotal is meaningful.
sales = sales_data()
products = np.array([True, False, True])
include = products & ~np.isnan(sales)
subtotals = np.sum(sales, axis=1, where=include, dtype=np.float64)
counts = include.sum(axis=1)
answer = np.where(counts > 0, subtotals, np.nan)
print("Books and Gifts subtotals:", answer)
print("Included known values:", counts)
np.testing.assert_allclose(answer[:3], [120, 100, 110])
assert np.isnan(answer[3])
assert np.nansum(answer) == 330
Expected output
Books and Gifts subtotals: [120. 100. 110.  nan]
Included known values: [2 2 2 0]
Practice in Google Colab
Open in Google Colab View on GitHub
All synthetic sample data is included. Run the examples, compare axes and masks, and complete the sales exercise. Save a copy in Drive before editing.
Continue with NumPy tutorials, axis reduction, array shapes and data types. Compare Pandas sum() when working with labelled tables. Reference: NumPy sum documentation.

Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials