Pandas max(): Maximum Values, Missing Data and Matching Records
DataFrame.max() returns the highest value down each column or across each row. Select comparable measures, decide how missing values affect the answer, and retrieve matching records separately. For grouped reports, include valid counts so an unknown maximum is not mistaken for zero.
| Question | Approach |
|---|---|
| Maximum per selected column | max(axis=0) |
| Maximum per row | max(axis=1) |
| One maximum across a numeric table | max(axis=None) |
| Require complete observations | max(skipna=False) |
| First maximum label | idxmax(), after checking known values |
| All matching records | Compare values with their maximum |
Create the Student DataFrame
This sample includes names, numeric IDs and two subject scores. A numeric ID is not a score, so select the subjects deliberately when comparing marks. For more practice, use the student sample-data page.
import pandas as pd

def student_data():
    return pd.DataFrame({"NAME": ["Ravi", "Raju", "Alex", "Ron", "King", "Jack"],
                         "ID": [1, 2, 3, 4, 5, 6],
                         "MATH": [80, 40, 70, 70, 70, 30],
                         "ENGLISH": [80, 70, 40, 50, 60, 30]})

df = student_data()
print(df)
assert df.shape == (6, 4)
Expected output
   NAME  ID  MATH  ENGLISH
0  Ravi   1    80       80
1  Raju   2    40       70
2  Alex   3    70       40
3   Ron   4    70       50
4  King   5    70       60
5  Jack   6    30       30
Column Maximums with axis=0
The default axis=0 returns one maximum for each column. Text is compared lexicographically, so NAME returns Ron rather than a mark. Select MATH and ENGLISH to answer the score question. max returns values; it does not identify the student.
df = student_data()
print("All columns:")
print(df.max(axis=0))
print("Score columns:")
print(df[["MATH", "ENGLISH"]].max(axis=0))
assert df["MATH"].max() == df["ENGLISH"].max() == 80
Expected output
All columns:
NAME       Ron
ID           6
MATH        80
ENGLISH     80
dtype: object
Score columns:
MATH       80
ENGLISH    80
dtype: int64
Find the Record with the Highest MATH Score
Compare the score column with its maximum to retain the complete matching record. The same Boolean filter retains every tie. Use loc to select rows and specific report columns.
df = student_data()
highest = df["MATH"].max()
result = df.loc[df["MATH"].eq(highest)]
print("Maximum MATH:", highest)
print(result)
assert result["NAME"].tolist() == ["Ravi"]
Expected output
Maximum MATH: 80
   NAME  ID  MATH  ENGLISH
0  Ravi   1    80       80
Row Maximums with axis=1
axis=1 compares columns within each row. Only compare fields with compatible meaning and units. Including large numeric IDs could make an ID look like the highest score; row-wise comparison of mixed text and numbers can fail.
df = student_data()
df["HIGHEST_SCORE"] = df[["MATH", "ENGLISH"]].max(axis=1)
print(df[["NAME", "MATH", "ENGLISH", "HIGHEST_SCORE"]])
assert df["HIGHEST_SCORE"].tolist() == [80, 70, 70, 70, 70, 30]
Expected output
   NAME  MATH  ENGLISH  HIGHEST_SCORE
0  Ravi    80       80             80
1  Raju    40       70             70
2  Alex    70       40             70
3   Ron    70       50             70
4  King    70       60             70
5  Jack    30       30             30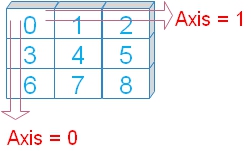
numeric_only Does Not Select Relevant Measures
numeric_only=True includes numeric and Boolean columns. It also includes ID here. Current Pandas defaults to numeric_only=False. Selecting score columns explicitly is clearer than assuming every numeric field belongs in the calculation.
df = student_data()
print("Numeric column maxima, including ID:")
print(df.max(numeric_only=True))
print("Row maxima including ID:")
print(df.max(axis=1, numeric_only=True))
assert df.max(axis=1, numeric_only=True).tolist() == [80, 70, 70, 70, 70, 30]
Expected output
Numeric column maxima, including ID:
ID          6
MATH       80
ENGLISH    80
dtype: int64
Row maxima including ID:
0    80
1    70
2    70
3    70
4    70
5    30
dtype: int64
One Maximum across Selected Rows and Columns
For a DataFrame, axis=None reduces across both axes and returns one scalar. Restrict the data to comparable score fields first. This is different from a Series of per-column maxima.
scores = student_data()[["MATH", "ENGLISH"]]
maximum = scores.max(axis=None)
print("Highest score anywhere:", maximum)
assert maximum == 80
Expected output
Highest score anywhere: 80skipna: Available Values versus Complete Data
skipna=True excludes missing values; it does not replace them. skipna=False propagates missing data in the relevant row or column. An available-value maximum can be useful, but it is not the maximum of a fully observed dataset.
df = student_data()
df.loc[2, "ENGLISH"] = float("nan")
scores = df[["MATH", "ENGLISH"]]
print("Available-value column maxima:")
print(scores.max(skipna=True))
print("Require complete columns:")
print(scores.max(skipna=False))
print("Require both scores in each row:")
print(scores.max(axis=1, skipna=False))
assert scores["ENGLISH"].max() == 80
assert pd.isna(scores["ENGLISH"].max(skipna=False))
Expected output
Available-value column maxima:
MATH       80.0
ENGLISH    80.0
dtype: float64
Require complete columns:
MATH       80.0
ENGLISH     NaN
dtype: float64
Require both scores in each row:
0    80.0
1    70.0
2     NaN
3    70.0
4    70.0
5    30.0
dtype: float64
Empty or All-Missing Data Has No Known Maximum
An all-missing numeric Series or an empty numeric Series has a missing maximum. Do not fill unknown scores with zero just to make a maximum appear: it would invent a score. Check for known observations before looking up a maximum record.
unknown = pd.Series([pd.NA, pd.NA], dtype="Float64")
empty = pd.Series([], dtype="float64")
print("All missing:", unknown.max())
print("Empty:", empty.max())
assert pd.isna(unknown.max()) and pd.isna(empty.max())
if unknown.notna().any():
    print(unknown.idxmax())
else:
    print("No known value; no maximum record to select.")
Expected output
All missing: <NA>
Empty: nan
No known value; no maximum record to select.
idxmax Returns a Label; Handle Ties Deliberately
max returns the value, while idxmax returns the label of the first maximum in the current order. It does not return an integer position or every tie. With unique labels, use loc to retrieve that record. Guard empty or all-missing data before idxmax. For all tied records, use the Boolean comparison.
df = student_data().set_index("ID")
df.loc[2, "MATH"] = 80
values = df["MATH"]
assert df.index.is_unique
first_label = values.idxmax()
print("First maximum label:", first_label)
print(df.loc[[first_label]])
all_ties = df.loc[values.eq(values.max())]
print("All tied records:")
print(all_ties)
assert first_label == 1
assert all_ties.index.tolist() == [1, 2]
Expected output
First maximum label: 1
    NAME  MATH  ENGLISH
ID
1   Ravi    80       80
All tied records:
    NAME  MATH  ENGLISH
ID
1   Ravi    80       80
2   Raju    80       70
Grouped Maximums for a MultiIndex
Use groupby() with level="math" for this hierarchical index. Grouping and max are separate operations. sort=False retains the first-seen group order.
index = pd.MultiIndex.from_arrays(
    [[1, 2, 3, 4, 5, 6], [80, 40, 70, 70, 70, 30], [80, 70, 40, 50, 60, 30]],
    names=["id", "math", "eng"])
marks = pd.Series([4, 2, 0, 8, 3, 4], name="marks", index=index)
result = marks.groupby(level="math", sort=False).max()
print(result)
assert result.to_dict() == {80: 4, 40: 2, 70: 8, 30: 4}
Expected output
math
80    4
40    2
70    8
30    4
Name: marks, dtype: int64
Convert Text Numbers before Finding the Maximum
Text values use text ordering: "9" sorts after "100", even though 9 is numerically smaller. Use to_numeric with a deliberate error policy, retain raw values and review invalid nonblank inputs. Missing values are not automatically invalid supplied measurements.
raw = pd.Series(["100", "20", "9", "bad", None], dtype="string")
print("Text maximum:", raw.max())
numeric = pd.to_numeric(raw, errors="coerce")
invalid = raw.notna() & numeric.isna()
print(pd.DataFrame({"raw": raw, "numeric": numeric, "invalid": invalid}))
print("Numeric maximum:", numeric.max())
assert numeric.max() == 100 and invalid.sum() == 1
Expected output
Text maximum: bad
    raw  numeric  invalid
0   100      100    False
1    20       20    False
2     9        9    False
3   bad     <NA>     True
4  <NA>     <NA>    False
Numeric maximum: 100
Maximum Dates and Durations
Datetime and Timedelta columns support maximums. Parse date text with to_datetime(), or convert elapsed minutes with to_timedelta(). A maximum date is the latest date; a maximum valid duration is the longest elapsed time.
dates = pd.to_datetime(pd.Series(["2024-03-01", "2024-01-15", None]), format="%Y-%m-%d")
durations = pd.to_timedelta(pd.Series([90, 30, 60]), unit="min")
print("Latest date:", dates.max())
print("Longest duration:", durations.max())
assert dates.max() == pd.Timestamp("2024-03-01")
assert durations.max() == pd.Timedelta(minutes=90)
Expected output
Latest date: 2024-03-01 00:00:00
Longest duration: 0 days 01:30:00
Practical Dataset: Highest Valid Order Value
This synthetic order dataset includes tied high values, a negative value and a missing amount. All amounts are in the same currency. A negative order value is invalid for this scenario; in a returns dataset it may be legitimate. Define the source policy before masking values.
def order_data():
    return pd.DataFrame({"order_id": [101, 102, 103, 104, 105, 106],
                         "category": ["Books", "Books", "Books", "Stationery", "Stationery", "Gifts"],
                         "amount": [120.5, 120.5, -10, 30.0, 45.0, None]})

orders = order_data()
orders["needs_review"] = orders["amount"].isna() | orders["amount"].lt(0)
orders["valid_amount"] = orders["amount"].mask(orders["needs_review"])
print(orders.to_string(index=False))
assert orders["needs_review"].sum() == 2
assert orders["valid_amount"].max() == 120.5
Expected output
 order_id   category  amount  needs_review  valid_amount
      101      Books   120.5         False         120.5
      102      Books   120.5         False         120.5
      103      Books   -10.0          True           NaN
      104 Stationery    30.0         False          30.0
      105 Stationery    45.0         False          45.0
      106      Gifts     NaN          True           NaN
Category Maximums with Completeness Counts
A category maximum is one largest valid order, not total category revenue. Keep Gifts in the report with a missing maximum and zero valid observations. A missing result does not mean zero revenue. Compare sum() when a total is needed.
orders = order_data()
orders["needs_review"] = orders["amount"].isna() | orders["amount"].lt(0)
orders["valid_amount"] = orders["amount"].mask(orders["needs_review"])
report = orders.groupby("category").agg(
    highest_order=("valid_amount", "max"), records=("order_id", "size"),
    valid_orders=("valid_amount", "count"), review_records=("needs_review", "sum"))
print(report)
assert report.loc["Books", "highest_order"] == 120.5
assert report.loc["Stationery", "highest_order"] == 45
assert pd.isna(report.loc["Gifts", "highest_order"])
assert report["records"].sum() == len(orders)
assert (report["valid_orders"] + report["review_records"]).equals(report["records"])
Expected output
            highest_order  records  valid_orders  review_records
category
Books               120.5        3             2               1
Gifts                 NaN        1             0               1
Stationery           45.0        2             2               0
Return All Orders Tied for Their Category Maximum
transform broadcasts each category maximum to its records. Compare valid values with the group maximum to retrieve all tied orders. Compare unrounded values; display rounding can create apparent ties that are not equal in the source.
orders = order_data()
valid = orders.loc[orders["amount"].notna() & orders["amount"].ge(0)].copy()
group_max = valid.groupby("category")["amount"].transform("max")
highest_orders = valid.loc[valid["amount"].eq(group_max)]
print(highest_orders.to_string(index=False))
assert highest_orders["order_id"].tolist() == [101, 102, 105]
Expected output
 order_id   category  amount
      101      Books   120.5
      102      Books   120.5
      105 Stationery    45.0
Maximum versus the Top Several Orders
max returns a scalar extreme, while nlargest returns ranked records. keep="all" can include more than n records when ties occur at the cutoff. Decide whether all ties or a fixed-length result fits the report.
orders = order_data()
valid = orders.loc[orders["amount"].notna() & orders["amount"].ge(0)]
top = valid.nlargest(1, "amount", keep="all")
print(top.to_string(index=False))
assert top["order_id"].tolist() == [101, 102]
Expected output
 order_id category  amount
      101    Books   120.5
      102    Books   120.5
Common Maximum-Value Problems
ID or unrelated field wins: select comparable measures. Text comparison fails: inspect types and convert text numbers. Unknown maximum: review missing values and valid counts. Only one tied row: idxmax returns the first label; use a Boolean filter for all ties. Wrong record from iloc: idxmax returns a label, so use loc with unique labels. Grouped maximum needed: groupby then max. Maximum treated as revenue: it is one extreme value, not the total. Use describe() and data cleaning to investigate unexpected extremes.
Exercise: Highest Score for Complete Student Records
Set Ravi ENGLISH to missing. Calculate a row maximum only when both scores are known, then find all students tied for the highest valid row maximum. Predict Ravi as missing and Raju, Alex, Ron and King tied at 70.
Exercise Solution
skipna=False requires complete observations for this exercise. Check the missing student and every tied record rather than only the scalar result.
df = student_data()
df.loc[0, "ENGLISH"] = float("nan")
df["HIGHEST_SCORE"] = df[["MATH", "ENGLISH"]].max(axis=1, skipna=False)
known = df["HIGHEST_SCORE"].notna()
highest = df.loc[known, "HIGHEST_SCORE"].max()
result = df.loc[known & df["HIGHEST_SCORE"].eq(highest)]
print(df[["NAME", "HIGHEST_SCORE"]])
print("Highest valid students:", result["NAME"].tolist())
assert pd.isna(df.loc[0, "HIGHEST_SCORE"])
assert highest == 70
assert result["NAME"].tolist() == ["Raju", "Alex", "Ron", "King"]
Expected output
   NAME  HIGHEST_SCORE
0  Ravi            NaN
1  Raju           70.0
2  Alex           70.0
3   Ron           70.0
4  King           70.0
5  Jack           30.0
Highest valid students: ['Raju', 'Alex', 'Ron', 'King']
Practice in Google Colab
Open in Google Colab View on GitHub
All synthetic sample data is included. Run the examples, compare maximum values with matching records, and try the exercise. Save a copy in Drive before making changes.
Continue with Data Exploration and Analysis, min(), mean(), sum() and std(). Reference: Pandas max documentation.

Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials