Pandas merge(): Join Tables and Validate Sales Reports
Use merge() to combine related tables by a key. Choose the join type, validate the expected relationship and review unmatched keys before calculating report totals.
Choose the join and its expected cardinality 🔝
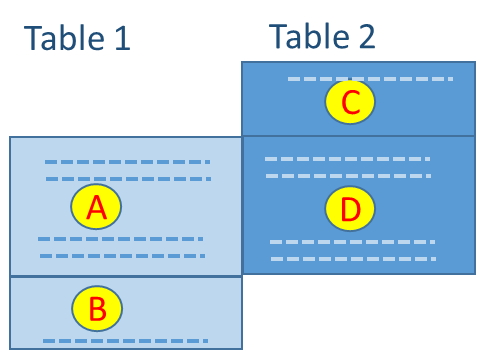
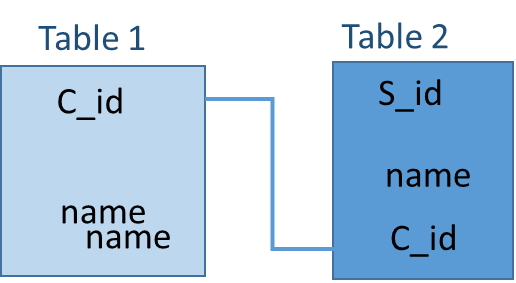 Use merge() to add columns from a related table using explicit keys. A left join keeps left records; inner keeps matches; right keeps right records; outer includes both sets of keys. Repeated keys can multiply rows. validate="many_to_one" checks a common sales-to-product relationship. indicator=True identifies the source of each result row. Specify on or left_on/right_on rather than relying on every common column name. copy is deprecated and ignored in Pandas 3; these examples omit it.
Create sales and product tables 🔝
One row is one sale in the left table and one product in the catalogue. Product keys in the catalogue must be unique. The sample uses the same sale and product concepts as the sample DataFrames page; all records needed for this notebook are embedded.
import pandas as pd
def sales_data():
    return pd.DataFrame({"sale_id": [1, 2, 3, 4, 5, 6, 7, 8, 9], "c_id": [2, 2, 1, 4, 2, 3, 2, 3, 2], "p_id": [3, 4, 3, 2, 3, 3, 2, 2, 3], "product": ["Monitor", "CPU", "Monitor", "RAM", "Monitor", "Monitor", "RAM", "RAM", "Monitor"], "qty": [2, 1, 3, 2, 3, 2, 3, 2, 2], "store": ["ABC", "DEF", "ABC", "DEF", "ABC", "DEF", "ABC", "DEF", "ABC"]})
def product_data():
    return pd.DataFrame({"p_id": [1, 2, 3, 4, 5, 6, 7, 8], "product": ["Hard Disk", "RAM", "Monitor", "CPU", "Keyboard", "Mouse", "Motherboard", "Power supply"], "price": [80, 90, 75, 55, 20, 10, 50, 20]})
sales, products = sales_data(), product_data()
print(sales)
print(products)
assert sales["sale_id"].is_unique and products["p_id"].is_unique
Expected output
   sale_id  c_id  p_id  product  qty store
0        1     2     3  Monitor    2   ABC
1        2     2     4      CPU    1   DEF
2        3     1     3  Monitor    3   ABC
3        4     4     2      RAM    2   DEF
4        5     2     3  Monitor    3   ABC
5        6     3     3  Monitor    2   DEF
6        7     2     2      RAM    3   ABC
7        8     3     2      RAM    2   DEF
8        9     2     3  Monitor    2   ABC
   p_id       product  price
0     1     Hard Disk     80
1     2           RAM     90
2     3       Monitor     75
3     4           CPU     55
4     5      Keyboard     20
5     6         Mouse     10
6     7   Motherboard     50
7     8  Power supply     20
Left join: keep every sale 🔝
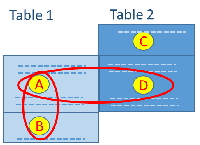 Join sales to the catalogue using p_id. Both tables have product, so default suffixes create product_x and product_y. Every sale has a match in this sample; the validated join preserves nine sale rows and twenty units.
sales, products = sales_data(), product_data()
joined = pd.merge(sales, products, on="p_id", how="left", validate="many_to_one")
print(joined)
assert len(joined) == 9
assert joined["qty"].sum() == 20
assert joined["price"].notna().all()
Expected output
   sale_id  c_id  p_id product_x  qty store product_y  price
0        1     2     3   Monitor    2   ABC   Monitor     75
1        2     2     4       CPU    1   DEF       CPU     55
2        3     1     3   Monitor    3   ABC   Monitor     75
3        4     4     2       RAM    2   DEF       RAM     90
4        5     2     3   Monitor    3   ABC   Monitor     75
5        6     3     3   Monitor    2   DEF   Monitor     75
6        7     2     2       RAM    3   ABC       RAM     90
7        8     3     2       RAM    2   DEF       RAM     90
8        9     2     3   Monitor    2   ABC   Monitor     75
Reverse the left join to find products without sales 🔝
Put products on the left to retain the full catalogue. With one catalogue row and several sales per product, validate="one_to_many" expresses the relationship. indicator is more reliable for identifying unmatched rows than testing whether an arbitrary measure is missing.
sales, products = sales_data(), product_data()
catalogue = products.merge(sales, on="p_id", how="left", validate="one_to_many", indicator=True)
unsold = catalogue.loc[catalogue["_merge"].eq("left_only")]
print(catalogue)
print("Products without sales:")
print(unsold[["p_id", "product_x", "price"]])
assert unsold["p_id"].tolist() == [1, 5, 6, 7, 8]
assert len(catalogue) == 14
Expected output
    p_id     product_x  price  sale_id  c_id product_y  qty store     _merge
0      1     Hard Disk     80      NaN   NaN       NaN  NaN   NaN  left_only
1      2           RAM     90      4.0   4.0       RAM  2.0   DEF       both
2      2           RAM     90      7.0   2.0       RAM  3.0   ABC       both
3      2           RAM     90      8.0   3.0       RAM  2.0   DEF       both
4      3       Monitor     75      1.0   2.0   Monitor  2.0   ABC       both
5      3       Monitor     75      3.0   1.0   Monitor  3.0   ABC       both
6      3       Monitor     75      5.0   2.0   Monitor  3.0   ABC       both
7      3       Monitor     75      6.0   3.0   Monitor  2.0   DEF       both
8      3       Monitor     75      9.0   2.0   Monitor  2.0   ABC       both
9      4           CPU     55      2.0   2.0       CPU  1.0   DEF       both
10     5      Keyboard     20      NaN   NaN       NaN  NaN   NaN  left_only
11     6         Mouse     10      NaN   NaN       NaN  NaN   NaN  left_only
12     7   Motherboard     50      NaN   NaN       NaN  NaN   NaN  left_only
13     8  Power supply     20      NaN   NaN       NaN  NaN   NaN  left_only
Products without sales:
    p_id     product_x  price
0      1     Hard Disk     80
10     5      Keyboard     20
11     6         Mouse     10
12     7   Motherboard     50
13     8  Power supply     20
Right join: retain the catalogue 🔝
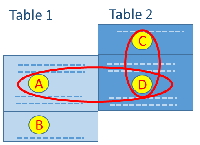 A right join with products on the right also includes products without sales. Do not infer a sale from a catalogue-only row; it has no sale_id.
sales, products = sales_data(), product_data()
right_join = sales.merge(products, on="p_id", how="right", validate="many_to_one", indicator=True)
print(right_join)
assert len(right_join) == 14
assert right_join["_merge"].eq("right_only").sum() == 5
Expected output
    sale_id  c_id  p_id product_x  qty store     product_y  price      _merge
0       NaN   NaN     1       NaN  NaN   NaN     Hard Disk     80  right_only
1       4.0   4.0     2       RAM  2.0   DEF           RAM     90        both
2       7.0   2.0     2       RAM  3.0   ABC           RAM     90        both
3       8.0   3.0     2       RAM  2.0   DEF           RAM     90        both
4       1.0   2.0     3   Monitor  2.0   ABC       Monitor     75        both
5       3.0   1.0     3   Monitor  3.0   ABC       Monitor     75        both
6       5.0   2.0     3   Monitor  3.0   ABC       Monitor     75        both
7       6.0   3.0     3   Monitor  2.0   DEF       Monitor     75        both
8       9.0   2.0     3   Monitor  2.0   ABC       Monitor     75        both
9       2.0   2.0     4       CPU  1.0   DEF           CPU     55        both
10      NaN   NaN     5       NaN  NaN   NaN      Keyboard     20  right_only
11      NaN   NaN     6       NaN  NaN   NaN         Mouse     10  right_only
12      NaN   NaN     7       NaN  NaN   NaN   Motherboard     50  right_only
13      NaN   NaN     8       NaN  NaN   NaN  Power supply     20  right_only
Inner join: retain matching keys 🔝
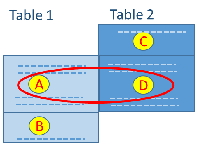 An inner join can discard unmatched sales. Audit a left join first when missing lookup records need investigation. Here all original sales match.
sales, products = sales_data(), product_data()
inner = sales.merge(products, on="p_id", how="inner", validate="many_to_one")
print(inner)
assert len(inner) == 9
assert inner["sale_id"].is_unique
Expected output
   sale_id  c_id  p_id product_x  qty store product_y  price
0        1     2     3   Monitor    2   ABC   Monitor     75
1        2     2     4       CPU    1   DEF       CPU     55
2        3     1     3   Monitor    3   ABC   Monitor     75
3        4     4     2       RAM    2   DEF       RAM     90
4        5     2     3   Monitor    3   ABC   Monitor     75
5        6     3     3   Monitor    2   DEF   Monitor     75
6        7     2     2       RAM    3   ABC       RAM     90
7        8     3     2       RAM    2   DEF       RAM     90
8        9     2     3   Monitor    2   ABC   Monitor     75
Outer join: inspect both unmatched sides 🔝
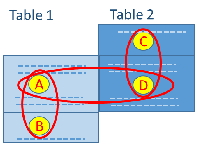 Add a sale with a product key absent from the catalogue. An outer join shows that sale and catalogue products without sales. _merge contains left_only, right_only and both.
sales, products = sales_data(), product_data()
extra = pd.DataFrame({"sale_id": [10], "c_id": [4], "p_id": [99], "product": ["Unknown"], "qty": [1], "store": ["ABC"]})
extended = pd.concat([sales, extra], ignore_index=True)
outer = extended.merge(products, on="p_id", how="outer", validate="many_to_one", indicator=True)
print(outer)
print(outer["_merge"].value_counts())
assert outer["_merge"].eq("left_only").sum() == 1
assert outer["_merge"].eq("right_only").sum() == 5
assert outer["_merge"].eq("both").sum() == 9
Expected output
    sale_id  c_id  p_id product_x  qty store     product_y  price      _merge
0       NaN   NaN     1       NaN  NaN   NaN     Hard Disk   80.0  right_only
1       4.0   4.0     2       RAM  2.0   DEF           RAM   90.0        both
2       7.0   2.0     2       RAM  3.0   ABC           RAM   90.0        both
3       8.0   3.0     2       RAM  2.0   DEF           RAM   90.0        both
4       1.0   2.0     3   Monitor  2.0   ABC       Monitor   75.0        both
5       3.0   1.0     3   Monitor  3.0   ABC       Monitor   75.0        both
6       5.0   2.0     3   Monitor  3.0   ABC       Monitor   75.0        both
7       6.0   3.0     3   Monitor  2.0   DEF       Monitor   75.0        both
8       9.0   2.0     3   Monitor  2.0   ABC       Monitor   75.0        both
9       2.0   2.0     4       CPU  1.0   DEF           CPU   55.0        both
10      NaN   NaN     5       NaN  NaN   NaN      Keyboard   20.0  right_only
11      NaN   NaN     6       NaN  NaN   NaN         Mouse   10.0  right_only
12      NaN   NaN     7       NaN  NaN   NaN   Motherboard   50.0  right_only
13      NaN   NaN     8       NaN  NaN   NaN  Power supply   20.0  right_only
14     10.0   4.0    99   Unknown  1.0   ABC           NaN    NaN   left_only
_merge
both          9
right_only    5
left_only     1
Name: count, dtype: int64
Use different key names and meaningful suffixes 🔝
left_on and right_on identify differently named keys. Use suffixes to retain the provenance of overlapping labels, then compare the labels rather than silently choosing one.
sales = sales_data().rename(columns={"p_id": "product_id"})
products = product_data()
joined = sales.merge(products, left_on="product_id", right_on="p_id", how="left", suffixes=("_sale", "_catalogue"), validate="many_to_one")
print(joined[["sale_id", "product_id", "p_id", "product_sale", "product_catalogue", "price"]])
assert joined["product_sale"].eq(joined["product_catalogue"]).all()
Expected output
   sale_id  product_id  p_id product_sale product_catalogue  price
0        1           3     3      Monitor           Monitor     75
1        2           4     4          CPU               CPU     55
2        3           3     3      Monitor           Monitor     75
3        4           2     2          RAM               RAM     90
4        5           3     3      Monitor           Monitor     75
5        6           3     3      Monitor           Monitor     75
6        7           2     2          RAM               RAM     90
7        8           2     2          RAM               RAM     90
8        9           3     3      Monitor           Monitor     75
Join on a composite key 🔝
If prices vary by store, p_id alone is insufficient. A product-store pair defines the lookup key. Validate that pair and inspect matches before calculating revenue.
sales = sales_data()
prices = pd.DataFrame({"p_id": [2, 2, 3, 3, 4], "store": ["ABC", "DEF", "ABC", "DEF", "DEF"], "price": [90, 95, 75, 80, 55]})
joined = sales.merge(prices, on=["p_id", "store"], how="left", validate="many_to_one", indicator=True)
print(joined[["sale_id", "p_id", "store", "qty", "price", "_merge"]])
assert joined["_merge"].eq("both").all()
assert joined.loc[joined["sale_id"].eq(6), "price"].iloc[0] == 80
Expected output
   sale_id  p_id store  qty  price _merge
0        1     3   ABC    2     75   both
1        2     4   DEF    1     55   both
2        3     3   ABC    3     75   both
3        4     2   DEF    2     95   both
4        5     3   ABC    3     75   both
5        6     3   DEF    2     80   both
6        7     2   ABC    3     90   both
7        8     2   DEF    2     95   both
8        9     3   ABC    2     75   both
Join to an indexed lookup 🔝
right_index=True joins a left key to the right index. Ensure the lookup index is unique. For an index-to-index join, use both left_index=True and right_index=True. See set_index() and reset_index().
sales = sales_data()
lookup = product_data().set_index("p_id")[["price"]]
joined = sales.merge(lookup, left_on="p_id", right_index=True, how="left", validate="many_to_one")
print(joined)
assert len(joined) == len(sales)
assert lookup.index.is_unique
Expected output
   sale_id  c_id  p_id  product  qty store  price
0        1     2     3  Monitor    2   ABC     75
1        2     2     4      CPU    1   DEF     55
2        3     1     3  Monitor    3   ABC     75
3        4     4     2      RAM    2   DEF     90
4        5     2     3  Monitor    3   ABC     75
5        6     3     3  Monitor    2   DEF     75
6        7     2     2      RAM    3   ABC     90
7        8     3     2      RAM    2   DEF     90
8        9     2     3  Monitor    2   ABC     75
Detect a lookup that would multiply sales 🔝
Two catalogue records for the same key can double matching sales. validate raises MergeError before such a join is used. Do not fix conflicting records by arbitrarily keeping the first; investigate the intended product key or version.
sales, products = sales_data(), product_data()
duplicate_lookup = pd.concat([products, products.loc[products["p_id"].eq(3)]], ignore_index=True)
try:
    sales.merge(duplicate_lookup, on="p_id", how="left", validate="many_to_one")
except pd.errors.MergeError:
    print("Catalogue contains repeated product keys; review before joining.")
unvalidated = sales.merge(duplicate_lookup, on="p_id", how="left")
print("Source sales:", len(sales), "Unvalidated result rows:", len(unvalidated))
assert len(unvalidated) == 14
assert len(sales) == 9
Expected output
Catalogue contains repeated product keys; review before joining.
Source sales: 9 Unvalidated result rows: 14
Separate missing keys before a business join 🔝
Pandas matches missing keys to missing keys, unlike ordinary SQL equality joins. A missing identifier does not establish a shared entity. This demonstration shows the behaviour, then separates unknown keys for review.
left = pd.DataFrame({"key": [1, None], "sale": ["known", "unknown"]})
right = pd.DataFrame({"key": [1, None], "label": ["Product A", "Unknown lookup"]})
print(left.merge(right, on="key", how="left", indicator=True))
review = left.loc[left["key"].isna()].copy()
safe = left.loc[left["key"].notna()].merge(right.loc[right["key"].notna()], on="key", how="left", validate="many_to_one")
print("Known keys:")
print(safe)
print("Review:")
print(review)
assert len(safe) == 1 and len(review) == 1
Expected output
   key     sale           label _merge
0  1.0    known       Product A   both
1  NaN  unknown  Unknown lookup   both
Known keys:
   key   sale      label
0  1.0  known  Product A
Review:
   key     sale
1  NaN  unknown
Create every combination with a cross join 🔝
A cross join needs no key. Three students and two subjects create six combinations. The result grows as left rows multiplied by right rows; check the expected size before expanding large tables.
students = pd.DataFrame({"NAME": ["Alex", "Ravi", "John"], "AGE": [22, 23, 21]})
subjects = pd.DataFrame({"SUBJECT": ["Hindi", "English"]})
combinations = students.merge(subjects, how="cross")
print(combinations)
assert len(combinations) == len(students) * len(subjects) == 6
Expected output
   NAME  AGE  SUBJECT
0  Alex   22    Hindi
1  Alex   22  English
2  Ravi   23    Hindi
3  Ravi   23  English
4  John   21    Hindi
5  John   21  English
Build a checked revenue report 🔝
In this synthetic example, catalogue price is the unit price used for each sale. Real historical revenue may require the price stored on the sale or an effective-dated price lookup. Separate unmatched rows, verify name agreement and calculate only from known valid quantities and prices.
sales, products = sales_data(), product_data()
assert sales["p_id"].notna().all() and products["p_id"].notna().all()
joined = sales.merge(products, on="p_id", how="left", suffixes=("_sale", "_catalogue"), validate="many_to_one", indicator=True)
accepted = joined.loc[joined["_merge"].eq("both")].copy()
review = joined.loc[~joined["_merge"].eq("both")].copy()
assert len(joined) == len(sales)
assert accepted["product_sale"].eq(accepted["product_catalogue"]).all()
assert accepted[["qty", "price"]].notna().all().all()
assert accepted["qty"].ge(0).all() and accepted["price"].ge(0).all()
accepted["revenue"] = accepted["qty"] * accepted["price"]
summary = accepted.groupby("product_catalogue", as_index=False).agg(sales_rows=("sale_id", "size"), units=("qty", "sum"), revenue=("revenue", "sum"))
print(summary)
print("Unmatched sales:", len(review))
assert summary["sales_rows"].sum() == 9
assert summary["units"].sum() == 20
assert summary["revenue"].sum() == 1585
Expected output
  product_catalogue  sales_rows  units  revenue
0               CPU           1      1       55
1           Monitor           5     12      900
2               RAM           3      7      630
Unmatched sales: 0
Reconcile and export the report 🔝
The known sample revenue is Monitor 900, RAM 630 and CPU 55. Check grouped totals against the joined sale rows. See groupby(), the reporting exercise and Input and Output.
export = summary.sort_values("revenue", ascending=False)
assert export["revenue"].sum() == accepted["revenue"].sum()
print(export.to_csv(index=False).rstrip())
# Optional Colab export:
# export.to_csv("joined_sales_report.csv", index=False)
Expected output
product_catalogue,sales_rows,units,revenue
Monitor,5,12,900
RAM,3,7,630
CPU,1,1,55
Common questions 🔝
Why did rows multiply? Keys repeated on one or both sides; choose a cardinality and validate it. many_to_many permits repeated keys without checking uniqueness. Why did rows disappear? An inner join omits unmatched keys. Why are prices missing? Inspect indicator and key values; do not automatically fill them with zero. Why does the key type matter? Align types deliberately and preserve identifiers with leading zeros. Why do labels have suffixes? Both sources contain a non-key column with the same name. How do I keep source order? Join types have defined key-order behaviour; explicitly sort the final report when ordering matters. How do I add rows instead? Use pd.concat(), which combines records rather than matching business keys. For key inspection see duplicated() and Data Cleaning.
Exercise: review a sale with an unknown product 🔝
Add a sale with sale_id 10, product key 99 and quantity 2. Use a validated left join and indicator. Predict the joined count, unmatched sale count and known revenue without assigning a made-up price.
Exercise solution 🔝
All ten sales are retained; one needs product review. The known revenue from nine matched sales remains 1585, so it is not a complete revenue total for all ten sales.
sales, products = sales_data(), product_data()
extra = pd.DataFrame({"sale_id": [10], "c_id": [4], "p_id": [99], "product": ["Unknown"], "qty": [2], "store": ["ABC"]})
extended = pd.concat([sales, extra], ignore_index=True)
answer = extended.merge(products, on="p_id", how="left", validate="many_to_one", indicator=True)
matched = answer.loc[answer["_merge"].eq("both")].copy()
unknown = answer.loc[answer["_merge"].eq("left_only")].copy()
known_revenue = (matched["qty"] * matched["price"]).sum()
print("Joined sales:", len(answer))
print("Unmatched sales:", len(unknown))
print("Known revenue:", known_revenue)
assert len(answer) == 10 and len(unknown) == 1
assert known_revenue == 1585
Expected output
Joined sales: 10
Unmatched sales: 1
Known revenue: 1585.0
Practice in Google Colab 🔝
Open in Google Colab View on GitHub
Run the examples in order, change join keys and catalogue records, then inspect matches and report totals. Save your own copy to keep edits. All sample tables are included in the notebook.
Continue with the Data Cleaning hub, where(), loc, at, NumPy where(), fillna() and iloc.
Reference: Pandas DataFrame.merge documentation.

Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials