Pandas to_sql(): Write a DataFrame to MySQL and Verify the Result
Use to_sql() to write DataFrame records to a database. For MySQL, use a SQLAlchemy engine with a compatible driver, choose how to handle an existing table, and read the stored records back to verify the import.
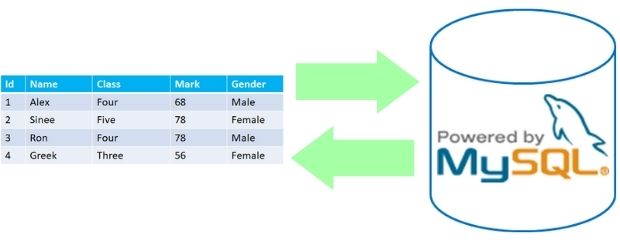
For browser practice, the notebook starts with SQLite. MySQL requires a database server; the connection and schema behaviour differ.
Show Table of ContentsVideo: DataFrame, CSV and Excel to MySQL
This earlier demonstration includes replace operations. Follow the current examples below and use replace only for disposable tables; it drops and recreates the table.
Start with a Runnable SQLite Example
This in-memory database is recreated each time this cell runs. The later cells reuse its connection. SQLite needs no server, so it is convenient for learning in Colab.
import pandas as pd
import sqlite3
from io import StringIO

if "conn" in globals():
    conn.close()
conn = sqlite3.connect(":memory:")
df = pd.DataFrame({"student_id": [1, 2, 3], "name": ["Ravi", "Alex", "King"], "mark": [80, 70, 60]})
df.to_sql("student_demo", conn, if_exists="fail", index=False)
saved = pd.read_sql_query("SELECT * FROM student_demo ORDER BY student_id", conn)
pd.testing.assert_frame_equal(saved, df)
print(saved.to_string(index=False))
print("Rows and values verified.")
Expected output
 student_id name  mark
          1 Ravi    80
          2 Alex    70
          3 King    60
Rows and values verified.
Choose the to_sql Parameters
| Parameter | Purpose |
|---|---|
| name / con | Fixed table name and database engine or connection. Do not accept unchecked table names from user input. |
| if_exists | fail raises an error if a table exists; append inserts rows; replace drops and recreates the table. Newer Pandas also supports delete_rows, which removes records before inserting while retaining the existing table; check your installed version. |
| index / index_label | index=True writes the DataFrame index as a column; index_label names it. Usually choose index=False when a real ID column already exists. |
| dtype | SQLAlchemy types for SQLAlchemy connections; SQLite type strings for a sqlite3 connection. |
| chunksize / method | Batch size and insert strategy. method='multi' is driver-dependent; benchmark before claiming it is faster. |
Creating a SQL table from a DataFrame does not automatically establish primary keys or business constraints. Use an intentionally defined schema for durable applications.
Test fail, append and replace
These operations affect only the disposable practice table. Append does not deduplicate or update existing records. Replace is not an UPDATE statement and can remove constraints and indexes.
try:
    df.to_sql("student_demo", conn, if_exists="fail", index=False)
except ValueError:
    print("fail: existing table was protected.")
new_student = pd.DataFrame({"student_id": [4], "name": ["Ron"], "mark": [65]})
new_student.to_sql("student_demo", conn, if_exists="append", index=False)
print("After append:", pd.read_sql_query("SELECT COUNT(*) AS n FROM student_demo", conn).iloc[0, 0])
df.to_sql("student_demo", conn, if_exists="replace", index=False)
print("After replacing disposable table:", pd.read_sql_query("SELECT COUNT(*) AS n FROM student_demo", conn).iloc[0, 0])
Expected output
fail: existing table was protected.
After append: 4
After replacing disposable table: 3
Use index_label When the Index Is Meaningful
For an existing table, index=False omits the index column; the database then applies its defaults and constraints. It does not guarantee that NULL will be inserted.
indexed = df.set_index("student_id")
indexed.to_sql("indexed_demo", conn, if_exists="replace", index=True, index_label="student_id")
print(pd.read_sql_query("SELECT * FROM indexed_demo ORDER BY student_id", conn).to_string(index=False))
Expected output
 student_id name  mark
          1 Ravi    80
          2 Alex    70
          3 King    60
Convert Dates and Validate Before Writing
Use an explicit input format. Coerce exposes invalid values as NaT; inspect them before export. Missing values normally become SQL NULL. Do not teach errors="ignore" as the current date-conversion approach.
dated = pd.DataFrame({"record_id": [1, 2], "c_date": ["01.10.2026", "invalid"]})
dated["c_date"] = pd.to_datetime(dated["c_date"], format="%d.%m.%Y", errors="coerce")
print("Invalid or missing dates:", int(dated["c_date"].isna().sum()))
valid_dates = dated.loc[dated["c_date"].notna()].copy()
valid_dates.to_sql("date_demo", conn, if_exists="replace", index=False)
print("Valid rows saved:", len(pd.read_sql_query("SELECT * FROM date_demo", conn)))
Expected output
Invalid or missing dates: 1
Valid rows saved: 1
Read CSV Data and Verify the Export
The synthetic CSV is embedded so you can run this example without uploading a file. For your own CSV, upload it in Colab and use pd.read_csv("your_file.csv").
csv_text = "student_id,name,mark\n10,Ravi,80\n11,Alex,70\n"
csv_df = pd.read_csv(StringIO(csv_text))
assert csv_df["student_id"].is_unique
csv_df.to_sql("csv_demo", conn, if_exists="replace", index=False, chunksize=100)
csv_saved = pd.read_sql_query("SELECT * FROM csv_demo ORDER BY student_id", conn)
pd.testing.assert_frame_equal(csv_saved, csv_df)
print(csv_saved.to_string(index=False))
Expected output
 student_id name  mark
         10 Ravi    80
         11 Alex    70
Create a Downloadable SQLite Database
This writes only to a dedicated demo file. Download it through the Colab Files sidebar; keeping a notebook does not keep its runtime files.
with sqlite3.connect("pandas_to_sql_practice.db") as file_conn:
    csv_df.to_sql("student_demo", file_conn, if_exists="replace", index=False)
    total = pd.read_sql_query("SELECT COUNT(*) AS n FROM student_demo", file_conn).iloc[0, 0]
print("Created pandas_to_sql_practice.db with", total, "rows.")
Expected output
Created pandas_to_sql_practice.db with 2 rows.Connect to MySQL with SQLAlchemy
Install sqlalchemy and pymysql in your environment, for example with %pip install sqlalchemy pymysql in Colab. The mysqlclient driver remains an alternative using mysql+mysqldb.
Create the database first. Set MYSQL_HOST, MYSQL_PORT, MYSQL_USER and MYSQL_DATABASE privately, or use Colab Secrets to obtain configuration. The password is prompted securely below. Never save credentials in notebook output.
Colab's localhost refers to its runtime, not your XAMPP computer. For local MySQL, run locally; for remote MySQL, use an authorised reachable server with the provider's required TLS configuration.
import os
from getpass import getpass
from sqlalchemy import create_engine, URL, text

url = URL.create(
    "mysql+pymysql",
    username=os.environ["MYSQL_USER"],
    password=getpass("MySQL password: "),
    host=os.environ["MYSQL_HOST"],
    port=int(os.environ.get("MYSQL_PORT", "3306")),
    database=os.environ["MYSQL_DATABASE"],
)
engine = create_engine(url, pool_pre_ping=True)
with engine.connect() as connection:
    print("Connection test:", connection.execute(text("SELECT 1")).scalar_one())
Write and Verify a MySQL Practice Table
Use a fresh demo table name. URL.create handles special characters in credentials without manual URL escaping. engine.begin commits on success and rolls back on exceptions where the database supports it; MySQL DDL can cause implicit commits, so do not promise rollback of table creation or replacement.
from sqlalchemy import Integer, String

mysql_df = pd.DataFrame({"student_id": [1, 2, 3], "name": ["Ravi", "Alex", "King"], "mark": [80, 70, 60]})
with engine.begin() as connection:
    mysql_df.to_sql(
        "student_export_demo", connection, if_exists="fail", index=False,
        dtype={"student_id": Integer(), "name": String(80), "mark": Integer()},
        chunksize=100,
    )
with engine.connect() as connection:
    stored = pd.read_sql_query(text("SELECT student_id, name, mark FROM student_export_demo ORDER BY student_id"), connection)
assert stored["student_id"].tolist() == mysql_df["student_id"].tolist()
assert stored["name"].tolist() == mysql_df["name"].tolist()
assert stored["mark"].tolist() == mysql_df["mark"].tolist()
print(stored.to_string(index=False))
print("MySQL rows and values verified.")
Specify SQL Types for Measurements
This retains the measurement-column example using a disposable table. Float is approximate; use an appropriate fixed-precision Numeric type for exact financial amounts and verify rounding requirements.
from sqlalchemy import Float

measurements = pd.DataFrame({"Sp_Mobile": [1.5, 2.5], "Sp_Desktop": [3.0, 4.0]})
with engine.begin() as connection:
    measurements.to_sql("measurement_demo", connection, if_exists="fail", index=False,
                        dtype={"Sp_Mobile": Float(), "Sp_Desktop": Float()})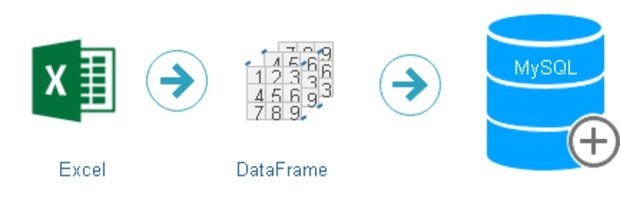
Excel to MySQL
Upload employees.xlsx in Colab or place it beside your local script. Install openpyxl if needed. Inspect the sheet and validate required columns before writing; this example expects student_id, name and mark.
excel_df = pd.read_excel("employees.xlsx", engine="openpyxl")
required = ["student_id", "name", "mark"]
if not set(required).issubset(excel_df.columns):
    raise ValueError("Excel file must include student_id, name and mark.")
if excel_df["student_id"].isna().any() or not excel_df["student_id"].is_unique:
    raise ValueError("Student IDs must be present and unique in this file.")
excel_df["mark"] = pd.to_numeric(excel_df["mark"], errors="raise")
with engine.begin() as connection:
    excel_df[required].to_sql("excel_student_demo", connection, if_exists="fail", index=False)
CSV to MySQL
Use the verified embedded CSV example above as the source. For production imports, compare IDs with the existing table and enforce unique constraints. Within-file uniqueness alone does not prevent a repeated import.
with engine.begin() as connection:
    csv_df.to_sql("csv_student_demo", connection, if_exists="fail", index=False)
with engine.connect() as connection:
    saved_csv = pd.read_sql_query(text("SELECT * FROM csv_student_demo ORDER BY student_id"), connection)
print(saved_csv.to_string(index=False))
Update Existing Records without Replacing the Table
Replace drops a table; it is not the right way to update marks in an established schema. Use parameterised SQL for record values. The following applies one update to the practice table; running it again adds another five marks.
with engine.begin() as connection:
    connection.execute(text("UPDATE student_export_demo SET mark = mark + :bonus WHERE student_id = :student_id"),
                       {"bonus": 5, "student_id": 1})
engine.dispose()
Common Problems and Checks
- Access denied: check database credentials, database privileges and permitted host.
- Connection refused or timeout: check server reachability; Colab cannot connect to your PC using localhost.
- Unknown index column: use index=False or deliberately align the destination schema.
- Duplicate key: check repeated imports and the destination's unique constraints; append is not an upsert.
- Table already exists: fail intentionally protects it. Review before choosing append or a new table name.
- Missing driver: install the driver matching the SQLAlchemy URL.
- Unexpected dates or SQL types: validate conversions, define dtype and read values back.
Do not treat the integer returned by to_sql as complete verification. Check destination rows, keys and values.
Practice Questions
- Write a DataFrame without its index and read it back.
- Append a new record, then explain what happens if you repeat the import.
- Verify IDs and values, not just a printed success message.
- Explain why replace can damage a production schema.
- Create a file-based SQLite database and download it.
- Identify which changes are needed to run the workflow against MySQL.
Practice in Google Colab
Upload the accompanying notebook to GitHub with its supplied filename; the buttons below work after upload. Save a copy in Drive and run the SQLite cells first. Optional MySQL cells are disabled until you configure a server.
Open in Google Colab View on GitHubContinue with Pandas Input and Output, MySQL connection setup, read_sql, read_sql_table and MySQL insert examples.
Use sample student files or the student SQL dump for further practice. For SQLite, see Colab to_sql practice, SQLite and the Kaggle dataset example. Date conversion: to_datetime.
References: Pandas to_sql and SQLAlchemy connections and transactions.

Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials