Pandas to_dict(): Choose the Right Dictionary Structure
DataFrame.to_dict() converts tabular data into Python structures. Choose the orientation according to what your code needs: a list of row records, an ID lookup, column arrays or a table structure that can be reconstructed.
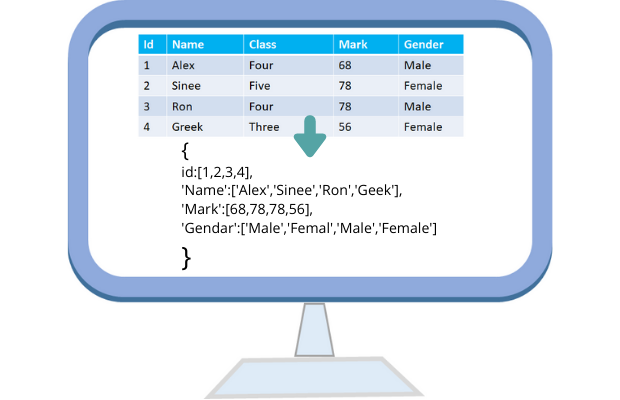
Create the Sample Student DataFrame
The three synthetic student records are used throughout the orientation examples. Each example calls the helper for fresh data. to_dict() creates Python objects in memory; it does not write a file or produce a JSON string.
import pandas as pd
from pprint import pprint

def student_data():
    return pd.DataFrame({
        "id": [1, 2, 3],
        "name": ["John Deo", "Max Ruin", "Arnold"],
        "class": ["Four", "Three", "Three"],
        "mark": [75, 85, 55],
        "gender": ["female", "male", "male"]
    })

df = student_data()
print(df)
Expected output
   id      name  class  mark  gender
0   1  John Deo   Four    75  female
1   2  Max Ruin  Three    85    male
2   3    Arnold  Three    55    male
Default orient="dict": Columns Then Index Labels
The outer keys are column names and the inner keys are index labels. Choose this when your code accesses one column and then a row label. A default RangeIndex produces keys 0, 1 and 2; these are not the student IDs. See Python dictionaries for accessing nested values.
df = student_data()
data = df.to_dict()
pprint(data, sort_dicts=False)
assert data == df.to_dict(orient="dict")
print("First mark:", data["mark"][0])
Expected output
{'id': {0: 1, 1: 2, 2: 3},
 'name': {0: 'John Deo', 1: 'Max Ruin', 2: 'Arnold'},
 'class': {0: 'Four', 1: 'Three', 2: 'Three'},
 'mark': {0: 75, 1: 85, 2: 55},
 'gender': {0: 'female', 1: 'male', 2: 'male'}}
First mark: 75
orient="list": One List per Column
Use this when the consumer expects parallel column arrays. Row index labels are omitted, but row order is preserved. The lists have the same length. Sorting or filtering before conversion changes their order or contents.
df = student_data()
data = df.to_dict(orient="list")
pprint(data, sort_dicts=False)
assert data["mark"] == [75, 85, 55]
Expected output
{'id': [1, 2, 3],
 'name': ['John Deo', 'Max Ruin', 'Arnold'],
 'class': ['Four', 'Three', 'Three'],
 'mark': [75, 85, 55],
 'gender': ['female', 'male', 'male']}
orient="series": Keep Pandas Series Values
The outer object is a dictionary, but each value is a Pandas Series with its index and dtype. Use it when downstream code still works with Pandas. It is not a plain list-based payload and cannot be directly encoded as ordinary JSON.
df = student_data()
data = df.to_dict(orient="series")
print("Value type:", type(data["mark"]).__name__)
print(data["mark"])
assert data["mark"].equals(df["mark"])
Expected output
Value type: Series
0    75
1    85
2    55
Name: mark, dtype: int64
orient="split": Separate Axes from Values
This structure has three keys: index, columns and data. It avoids repeating column names for every row and is useful when the consumer understands a table schema. Values are in column order, so retain the columns list with the data.
df = student_data()
data = df.to_dict(orient="split")
pprint(data, sort_dicts=False)
restored = pd.DataFrame(data["data"], index=data["index"], columns=data["columns"])
assert restored.equals(df)
Expected output
{'index': [0, 1, 2],
 'columns': ['id', 'name', 'class', 'mark', 'gender'],
 'data': [[1, 'John Deo', 'Four', 75, 'female'],
          [2, 'Max Ruin', 'Three', 85, 'male'],
          [3, 'Arnold', 'Three', 55, 'male']]}
orient="records": One Dictionary per Row
This returns a list of dictionaries rather than one dictionary. It is convenient for record-processing code and simple API payloads. The DataFrame index is omitted; a student ID remains present here because it is an ordinary column.
df = student_data()
records = df.to_dict(orient="records")
pprint(records, sort_dicts=False)
assert isinstance(records, list)
assert records[0]["id"] == 1
print("Second name:", records[1]["name"])
Expected output
[{'id': 1, 'name': 'John Deo', 'class': 'Four', 'mark': 75, 'gender': 'female'},
 {'id': 2, 'name': 'Max Ruin', 'class': 'Three', 'mark': 85, 'gender': 'male'},
 {'id': 3, 'name': 'Arnold', 'class': 'Three', 'mark': 55, 'gender': 'male'}]
Second name: Max Ruin
orient="index": A Lookup Keyed by Row Labels
Each outer key is an index label, and its value is a dictionary containing the row. Set a business key as the index if you want an ID lookup. verify_integrity=True rejects duplicate IDs instead of letting a lookup become ambiguous.
df = student_data().set_index("id", verify_integrity=True)
lookup = df.to_dict(orient="index")
pprint(lookup, sort_dicts=False)
print("Student 2:", lookup[2]["name"])
assert lookup[2]["mark"] == 85
Expected output
{1: {'name': 'John Deo', 'class': 'Four', 'mark': 75, 'gender': 'female'},
 2: {'name': 'Max Ruin', 'class': 'Three', 'mark': 85, 'gender': 'male'},
 3: {'name': 'Arnold', 'class': 'Three', 'mark': 55, 'gender': 'male'}}
Student 2: Max Ruin
orient="tight": Preserve Axis Names for Reconstruction
Tight adds index_names and column_names to the split-style data. Use DataFrame.from_dict(..., orient="tight") to rebuild the table, including named axes. This is a structural round trip; dictionary conversion does not generally preserve every dtype or custom object type.
df = student_data().set_index("id")
df.columns.name = "student_fields"
data = df.to_dict(orient="tight")
pprint(data, sort_dicts=False)
restored = pd.DataFrame.from_dict(data, orient="tight")
assert restored.equals(df)
assert restored.index.name == "id"
assert restored.columns.name == "student_fields"
Expected output
{'index': [1, 2, 3],
 'columns': ['name', 'class', 'mark', 'gender'],
 'data': [['John Deo', 'Four', 75, 'female'],
          ['Max Ruin', 'Three', 85, 'male'],
          ['Arnold', 'Three', 55, 'male']],
 'index_names': ['id'],
 'column_names': ['student_fields']}
index=False: Omit Index Metadata from split or tight
The index=False option is supported only with split and tight. Records already omit the index regardless of this option. If an index contains an important ID, move it into a column with reset_index() before building records.
df = student_data().set_index("id")
pprint(df.to_dict(orient="split", index=False), sort_dicts=False)
records_with_id = df.reset_index().to_dict(orient="records")
assert records_with_id[0]["id"] == 1
print("ID kept in records:", records_with_id[0]["id"])
Expected output
{'columns': ['name', 'class', 'mark', 'gender'],
 'data': [['John Deo', 'Four', 75, 'female'],
          ['Max Ruin', 'Three', 85, 'male'],
          ['Arnold', 'Three', 55, 'male']]}
ID kept in records: 1
into: Select the Mapping Type
The default mapping type is dict. You can supply a compatible mutable mapping class or instance. A defaultdict needs an initialized instance with a factory. Mapping type choices do not change the selected orientation.
from collections import OrderedDict, defaultdict

df = student_data()
ordered = df.to_dict(orient="list", into=OrderedDict)
print("Mapping type:", type(ordered).__name__)
print("Column order:", list(ordered))
records = df.to_dict(orient="records", into=defaultdict(list))
print("Record mapping type:", type(records[0]).__name__)
assert records[0]["id"] == 1
Expected output
Mapping type: OrderedDict
Column order: ['id', 'name', 'class', 'mark', 'gender']
Record mapping type: defaultdict
Check Duplicate Labels Before Building a Lookup
Dictionaries cannot preserve multiple values under one identical key. Index orientation requires unique row labels. Dictionary-shaped column exports also need unique column names to avoid lost columns. Check uniqueness before conversion; choose records or another representation when repeated row labels are intentional.
df = student_data()
df.index = ["group", "group", "other"]
print("Index unique:", df.index.is_unique)
try:
    df.to_dict(orient="index")
except ValueError:
    print("Cannot create an index lookup with duplicate row labels.")
records = df.to_dict(orient="records")
print("Rows retained as records:", len(records))
assert len(records) == 3
assert df.columns.is_unique
Expected output
Index unique: False
Cannot create an index lookup with duplicate row labels.
Rows retained as records: 3
Read CSV and Convert the Records
Once CSV data is a DataFrame, the conversion is the same. This in-memory CSV makes the example runnable immediately. Replace StringIO with your uploaded filename for your own data. Validate inferred types, missing values and selected fields first. See read_csv().
from io import StringIO

csv_text = "id,name,mark\n1,John Deo,75\n2,Max Ruin,85\n3,Arnold,55\n"
df = pd.read_csv(StringIO(csv_text))
records = df.to_dict(orient="records")
pprint(records, sort_dicts=False)
assert records[2]["mark"] == 55
Expected output
[{'id': 1, 'name': 'John Deo', 'mark': 75},
 {'id': 2, 'name': 'Max Ruin', 'mark': 85},
 {'id': 3, 'name': 'Arnold', 'mark': 55}]
Read Excel and Convert to a Dictionary
The same workflow applies to read_excel(). This example creates an in-memory workbook, reads it and exports records. For a real file, use its path or uploaded filename. The openpyxl engine is needed for this xlsx example.
from io import BytesIO

workbook = BytesIO()
student_data().to_excel(workbook, index=False, engine="openpyxl")
workbook.seek(0)
df = pd.read_excel(workbook, engine="openpyxl")
records = df.to_dict(orient="records")
print("Rows read from Excel:", len(records))
print("First record:", records[0])
assert len(records) == 3
Expected output
Rows read from Excel: 3
First record: {'id': 1, 'name': 'John Deo', 'class': 'Four', 'mark': 75, 'gender': 'female'}
Convert Database Query Results: SQLite Practice
A database query also produces a DataFrame. This SQLite example runs without credentials and illustrates conversion after a query. Select only the fields you intend to expose and use ORDER BY when record order matters. For other data sources, follow the Pandas Input and Output guide.
import sqlite3

with sqlite3.connect(":memory:") as connection:
    student_data().to_sql("student", connection, index=False)
    df = pd.read_sql_query(
        "SELECT id, name, mark FROM student ORDER BY id LIMIT 3", connection)
records = df.to_dict(orient="records")
pprint(records, sort_dicts=False)
assert records[0]["id"] == 1
Expected output
[{'id': 1, 'name': 'John Deo', 'mark': 75},
 {'id': 2, 'name': 'Max Ruin', 'mark': 85},
 {'id': 3, 'name': 'Arnold', 'mark': 55}]
Optional: Read Your MySQL Student Table
Use an authorized reachable MySQL server and a student table with id, name and mark columns. Set MYSQL_HOST, MYSQL_USER and MYSQL_DATABASE in your environment, and install SQLAlchemy and PyMySQL if needed. A Colab runtime cannot reach your XAMPP MySQL server through localhost. The notebook disables this optional cell so the other examples run without credentials. See MySQL with SQLAlchemy and the sample student SQL dump.
RUN_MYSQL = False

if RUN_MYSQL:
    import os
    from getpass import getpass
    from sqlalchemy import create_engine, text
    from sqlalchemy.engine import URL

    url = URL.create("mysql+pymysql", username=os.environ["MYSQL_USER"],
                     password=getpass("MySQL password: "),
                     host=os.environ["MYSQL_HOST"],
                     database=os.environ["MYSQL_DATABASE"])
    engine = create_engine(url)
    try:
        with engine.connect() as connection:
            df = pd.read_sql_query(text(
                "SELECT id, name, mark FROM student ORDER BY id LIMIT 3"), connection)
        print(df.to_dict(orient="records"))
    finally:
        engine.dispose()
A Python Dictionary Is Not Yet JSON
Missing numbers, timestamps and custom objects need a serialization policy. For a JSON record payload, to_json() can encode missing numeric values as null and dates in ISO format. Parse that JSON if your code needs plain Python records. This does not validate an external API schema; select and validate its expected fields separately.
import json

df = pd.DataFrame({"order_id": [1001, 1002],
                   "amount": [40.0, float("nan")],
                   "date": pd.to_datetime(["2026-01-01", "2026-01-02"])})
payload = df.to_json(orient="records", date_format="iso")
records = json.loads(payload)
pprint(records, sort_dicts=False)
assert records[1]["amount"] is None
assert isinstance(records[0]["date"], str)
Expected output
[{'order_id': 1001, 'amount': 40.0, 'date': '2026-01-01T00:00:00.000'},
 {'order_id': 1002, 'amount': None, 'date': '2026-01-02T00:00:00.000'}]
Practical Report: Export Only the Required Fields
A record payload should contain only the requested fields, not every column by default. This synthetic sales report selects order_id, category and revenue, then checks row count and a known total. Selecting a schema before export makes the result easier to consume and review.
sales = pd.DataFrame({"order_id": [1001, 1002, 1003],
                      "category": ["Office", "Books", "Stationery"],
                      "revenue": [550, 400, 200],
                      "internal_note": ["reviewed", "reviewed", "reviewed"]})
records = sales[["order_id", "category", "revenue"]].to_dict(orient="records")
pprint(records, sort_dicts=False)
assert len(records) == 3
assert all(set(row) == {"order_id", "category", "revenue"} for row in records)
assert sum(row["revenue"] for row in records) == 1150
Expected output
[{'order_id': 1001, 'category': 'Office', 'revenue': 550},
 {'order_id': 1002, 'category': 'Books', 'revenue': 400},
 {'order_id': 1003, 'category': 'Stationery', 'revenue': 200}]
Exercise: Build an ID-to-Mark Lookup
Create a plain dictionary mapping each student ID to their mark. Predict the result before running the solution. Expected result: {1: 75, 2: 85, 3: 55}. This is a Series conversion rather than a nested DataFrame conversion.
Exercise Solution
Set the unique ID as the index, select the mark Series and call its to_dict method. Check the key set and one known value.
df = student_data().set_index("id", verify_integrity=True)
marks = df["mark"].to_dict()
print(marks)
assert marks == {1: 75, 2: 85, 3: 55}
Expected output
{1: 75, 2: 85, 3: 55}Common Questions and Mistakes
Why is records a list? Each list item represents one row. Where did my index go? Records omit index labels; use reset_index first when they matter. Why did a column disappear? Check duplicate column names. Does a round trip restore every dtype? No; validate types after reconstruction. Can I send this to an API? Match the schema and serialization requirements first. What about large tables? Conversion materializes Python objects and can use substantial memory; avoid exporting unnecessary rows or fields. Which orientation should I choose? Records for row processing, index for unique-key lookups, list for column arrays, and tight for structural reconstruction.
Practice in Google Colab
Open in Google Colab View on GitHub
Run the orientation examples, inspect their types and practise reconstructing a table. Student data is included. MySQL is optional and disabled by default.
Related exports: to_excel(), to_string() and to_json(). Reference: Pandas DataFrame.to_dict documentation.

Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials