Pandas to_excel(): Create and Verify Excel Reports
DataFrame.to_excel() writes a table to an Excel workbook. Choose the fields, sheet names and formatting your reader needs, then read the workbook back to check its contents. Build a simple student export first, then create a sales workbook with detail and summary sheets.
Create Your First Excel File
to_excel() writes a DataFrame to a workbook. The default includes the DataFrame index; use index=False for a plain table when the index is not part of the report. The examples use a dedicated practice folder and read files back with read_excel() to check the result.
import pandas as pd
from pathlib import Path
from openpyxl import load_workbook

export_dir = Path("pandas_excel_practice")
export_dir.mkdir(exist_ok=True)

def student_data():
    return pd.DataFrame({"NAME": ["Ravi", "Raju", "Alex"],
                         "ID": [1, 2, 3], "MATH": [30, 40, 50],
                         "ENGLISH": [20, 30, 40]})

df = student_data()
path = export_dir / "students.xlsx"
df.to_excel(path, index=False, engine="openpyxl")
restored = pd.read_excel(path, engine="openpyxl")
print(restored)
assert restored.equals(df)
Expected output
   NAME  ID  MATH  ENGLISH
0  Ravi   1    30       20
1  Raju   2    40       30
2  Alex   3    50       40
Include or Omit the Index Column
With index=True, an extra column stores row labels. Name it with index_label when those labels are meaningful. With index=False, the workbook contains only DataFrame columns. Do not discard an ID stored in the index unless it is intentionally absent from the export.
df = student_data().set_index("ID")
path = export_dir / "with_index.xlsx"
df.to_excel(path, index=True, index_label="student_id", engine="openpyxl")
restored = pd.read_excel(path, engine="openpyxl")
print(restored.columns.tolist())
assert restored["student_id"].tolist() == [1, 2, 3]
Expected output
['student_id', 'NAME', 'MATH', 'ENGLISH']Choose a Path That Exists
Create the destination directory before writing. A relative path works in Colab; the path refers to its runtime filesystem. On Windows, a local path can be expressed as Path("D:/data/my_file.xlsx") or a raw string. Choose a real directory on your own machine. A new write to an existing filename replaces that workbook.
folder = export_dir / "reports"
folder.mkdir(exist_ok=True)
path = folder / "student_report.xlsx"
student_data().to_excel(path, index=False, engine="openpyxl")
print("Created:", path.as_posix())
assert path.is_file()
Expected output
Created: pandas_excel_practice/reports/student_report.xlsxna_rep: Display Missing Values Clearly
The default missing-value representation is a blank cell. na_rep="*" writes a visible marker. This changes the exported representation, not the source value. A marker can make a numeric report column contain text; document the convention for readers.
df = student_data()
df.loc[1, "MATH"] = float("nan")
path = export_dir / "missing_marks.xlsx"
df.to_excel(path, index=False, na_rep="*", engine="openpyxl")
wb = load_workbook(path)
print("Raju MATH cell:", wb.active["C3"].value)
assert wb.active["C3"].value == "*"
assert pd.isna(df.loc[1, "MATH"])
wb.close()
Expected output
Raju MATH cell: *Export Selected Columns in a Chosen Order
Use columns to select fields and their export order. The names must match the DataFrame exactly. Exporting only the required fields makes a report clearer and prevents accidental inclusion of unrelated data.
df = student_data()
path = export_dir / "selected_columns.xlsx"
df.to_excel(path, columns=["ID", "NAME"], index=False, engine="openpyxl")
restored = pd.read_excel(path, engine="openpyxl")
print(restored)
assert restored.columns.tolist() == ["ID", "NAME"]
Expected output
   ID  NAME
0   1  Ravi
1   2  Raju
2   3  Alex
Write Readable Header Aliases
A header list supplies aliases, with one alias for each exported column. It does not rename the source DataFrame. header=False omits the header row, which is useful only when the consumer already knows the schema.
df = student_data()
path = export_dir / "header_aliases.xlsx"
df.to_excel(path, columns=["ID", "NAME", "MATH"],
            header=["Student ID", "Student name", "Math score"],
            index=False, engine="openpyxl")
restored = pd.read_excel(path, engine="openpyxl")
print(restored.columns.tolist())
assert restored.columns.tolist() == ["Student ID", "Student name", "Math score"]
assert df.columns.tolist() == ["NAME", "ID", "MATH", "ENGLISH"]
Expected output
['Student ID', 'Student name', 'Math score']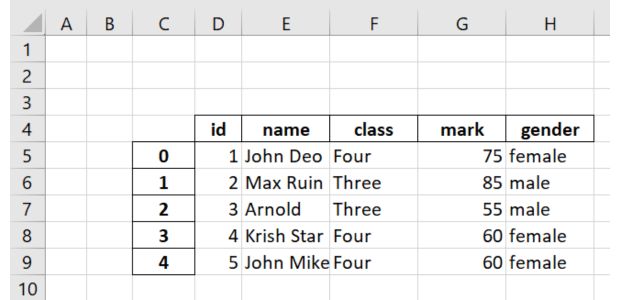
startrow and startcol: Position the Table
Both offsets are zero-based. With startrow=3 and startcol=2, the header begins at Excel cell C4. The first record begins at C5 when a header is written. This leaves room for a title or report notes above the table.
df = student_data()
path = export_dir / "offset_table.xlsx"
df.to_excel(path, index=False, startrow=3, startcol=2, engine="openpyxl")
wb = load_workbook(path)
sheet = wb.active
print("C4 header:", sheet["C4"].value)
print("C5 first name:", sheet["C5"].value)
assert sheet["C4"].value == "NAME"
assert sheet["C5"].value == "Ravi"
wb.close()
Expected output
C4 header: NAME
C5 first name: Ravi
Choose openpyxl or XlsxWriter
openpyxl can write new workbooks and load existing ones for append operations. XlsxWriter is useful for creating new workbooks with formatting and charts, but it does not append to existing workbooks. Specify the engine explicitly when the workflow depends on it. If an engine is missing in Colab, install the named package in a notebook cell before proceeding.
freeze_panes: Keep Headers and Key Columns Visible
The tuple describes the number of top rows and left columns to freeze. (1, 1) keeps the header row and first column visible. With openpyxl this becomes B2, the first unfrozen cell. Match the frozen boundary to any startrow/startcol offsets in your report.
df = student_data()
path = export_dir / "frozen_headers.xlsx"
df.to_excel(path, index=False, freeze_panes=(1, 1), engine="openpyxl")
wb = load_workbook(path)
print("First unfrozen cell:", wb.active.freeze_panes)
assert wb.active.freeze_panes == "B2"
wb.close()
Expected output
First unfrozen cell: B2float_format versus Excel Display Formatting
float_format="%.2f" writes rounded numeric values. If you need to keep the stored precision and change only what Excel displays, apply a cell number format instead. These approaches are different; decide whether rounding the stored value is intended.
df = pd.DataFrame({"amount": [0.1234, 12.3456]})
rounded_path = export_dir / "rounded_values.xlsx"
df.to_excel(rounded_path, index=False, float_format="%.2f", engine="openpyxl")
rounded = pd.read_excel(rounded_path, engine="openpyxl")
print("Written rounded values:", rounded["amount"].tolist())
assert rounded["amount"].tolist() == [0.12, 12.35]

precise_path = export_dir / "display_only.xlsx"
with pd.ExcelWriter(precise_path, engine="openpyxl") as writer:
    df.to_excel(writer, index=False, sheet_name="Amounts")
    for cell in writer.sheets["Amounts"]["A"][1:]:
        cell.number_format = "0.00"
restored = pd.read_excel(precise_path, engine="openpyxl")
assert restored["amount"].tolist() == df["amount"].tolist()
print("Stored precision preserved:", restored["amount"].tolist())
Expected output
Written rounded values: [0.12, 12.35]
Stored precision preserved: [0.1234, 12.3456]
Name a Worksheet
The default sheet name is Sheet1. Use a short descriptive name such as Students. Excel sheet names must be unique within the workbook, at most 31 characters and free of the invalid characters []:*?/\. Validate generated names before writing.
path = export_dir / "named_sheet.xlsx"
student_data().to_excel(path, index=False, sheet_name="Students", engine="openpyxl")
with pd.ExcelFile(path, engine="openpyxl") as workbook:
    print(workbook.sheet_names)
    assert workbook.sheet_names == ["Students"]
Expected output
['Students']Write Multiple Worksheets with ExcelWriter
Use one writer context and unique sheet names. Closing the context finalises the workbook. This creates two sheets from the same sample, preserving the multiple-worksheet workflow. Write mode replaces an existing workbook with the same path.
df = student_data()
path = export_dir / "multiple_sheets.xlsx"
with pd.ExcelWriter(path, engine="openpyxl") as writer:
    df.to_excel(writer, sheet_name="Students", index=False)
    df[["ID", "MATH", "ENGLISH"]].to_excel(writer, sheet_name="Scores", index=False)
with pd.ExcelFile(path, engine="openpyxl") as workbook:
    print(workbook.sheet_names)
    assert workbook.sheet_names == ["Students", "Scores"]
Expected output
['Students', 'Scores']Append Worksheets to an Existing Workbook
Use mode="a" with openpyxl. This example first creates a dedicated workbook, then adds two new sheets so rerunning the cell is predictable. Append mode adds sheets; it does not automatically append records within a sheet. Existing complex workbooks can contain features the engine does not preserve, so work on a copy.
df = student_data()
path = export_dir / "append_sheets.xlsx"
with pd.ExcelWriter(path, engine="openpyxl") as writer:
    df.to_excel(writer, sheet_name="Sheet_1", index=False)
    df.to_excel(writer, sheet_name="Sheet_2", index=False)
with pd.ExcelWriter(path, mode="a", engine="openpyxl") as writer:
    df.to_excel(writer, sheet_name="Sheet_3", index=False)
    df.to_excel(writer, sheet_name="Sheet_4", index=False)
with pd.ExcelFile(path, engine="openpyxl") as workbook:
    print(workbook.sheet_names)
    assert len(workbook.sheet_names) == 4
Expected output
['Sheet_1', 'Sheet_2', 'Sheet_3', 'Sheet_4']Decide What Happens When a Sheet Exists
The default append behaviour rejects a sheet-name collision. if_sheet_exists="replace" replaces that sheet; it is not a cell-by-cell update. Overlay writes into existing cells but can leave stale cells outside the new table. Choose the intended behaviour explicitly.
path = export_dir / "replace_sheet.xlsx"
student_data().to_excel(path, sheet_name="Students", index=False, engine="openpyxl")
updated = student_data().iloc[:2].copy()
with pd.ExcelWriter(path, mode="a", engine="openpyxl", if_sheet_exists="replace") as writer:
    updated.to_excel(writer, sheet_name="Students", index=False)
restored = pd.read_excel(path, sheet_name="Students", engine="openpyxl")
print("Rows in replaced sheet:", len(restored))
assert restored.equals(updated)
Expected output
Rows in replaced sheet: 2Practical Report: One Sheet per Student Class
Group a synthetic student table by class and write each class to its own sheet. The sample class names are already valid and unique; validate names for a real dataset. This workflow also applies after reading a database query into a DataFrame.
def class_data():
    return pd.DataFrame({"id": [1, 2, 3],
                         "name": ["John Deo", "Max Ruin", "Arnold"],
                         "class": ["Four", "Three", "Three"],
                         "mark": [75, 85, 55],
                         "gender": ["female", "male", "male"]})

df = class_data()
path = export_dir / "classes.xlsx"
with pd.ExcelWriter(path, engine="openpyxl") as writer:
    for class_name, group in df.groupby("class", sort=True):
        group.to_excel(writer, sheet_name=class_name, index=False)
with pd.ExcelFile(path, engine="openpyxl") as workbook:
    print(workbook.sheet_names)
    assert workbook.sheet_names == ["Four", "Three"]
assert len(pd.read_excel(path, sheet_name="Three", engine="openpyxl")) == 2
Expected output
['Four', 'Three']Export Database Query Results: Runnable SQLite Practice
Use read_sql() to create the DataFrame, then export it. This SQLite example needs no credentials and checks that the selected rows and columns reach the workbook. Use explicit fields and ORDER BY for a predictable report.
import sqlite3

with sqlite3.connect(":memory:") as connection:
    class_data().to_sql("student", connection, index=False)
    df = pd.read_sql_query(
        "SELECT id, name, mark FROM student ORDER BY id", connection)
path = export_dir / "database_students.xlsx"
df.to_excel(path, index=False, engine="openpyxl")
restored = pd.read_excel(path, engine="openpyxl")
print(restored)
assert restored.equals(df)
Expected output
   id      name  mark
0   1  John Deo    75
1   2  Max Ruin    85
2   3    Arnold    55
Optional MySQL Export with SQLAlchemy
Read from an authorized reachable server using SQLAlchemy, then write the result with the same export method. Set MYSQL_HOST, MYSQL_USER and MYSQL_DATABASE, and install SQLAlchemy and PyMySQL if needed. The notebook disables this cell so Run all requires no credentials. Colab localhost refers to its own runtime, not your XAMPP database. The student SQL dump provides sample table data.
RUN_MYSQL = False

if RUN_MYSQL:
    import os
    from getpass import getpass
    from sqlalchemy import create_engine, text
    from sqlalchemy.engine import URL

    url = URL.create("mysql+pymysql", username=os.environ["MYSQL_USER"],
                     password=getpass("MySQL password: "),
                     host=os.environ["MYSQL_HOST"], database=os.environ["MYSQL_DATABASE"])
    engine = create_engine(url)
    try:
        with engine.connect() as connection:
            df = pd.read_sql_query(text(
                "SELECT id, name, class, mark FROM student ORDER BY id"), connection)
        with pd.ExcelWriter(export_dir / "mysql_classes.xlsx", engine="openpyxl") as writer:
            for class_name, group in df.groupby("class"):
                group.to_excel(writer, sheet_name=str(class_name), index=False)
    finally:
        engine.dispose()
Filter Rows and Columns Before Export
Select the report contents before writing. This example exports only class Three and the class/name fields. After reading a CSV, the same selection works. The original test.csv sample is available for additional practice.
df = class_data()
selected = df.loc[df["class"].eq("Three"), ["class", "name"]]
path = export_dir / "selected_students.xlsx"
selected.to_excel(path, index=False, engine="openpyxl")
restored = pd.read_excel(path, engine="openpyxl")
print(restored)
assert len(restored) == 2
assert restored.columns.tolist() == ["class", "name"]
Expected output
   class      name
0  Three  Max Ruin
1  Three    Arnold
Practical Sales Workbook: Details and Summary
Write detailed records and a category summary to separate sheets. Check that the category totals reconcile with the detail revenue and that row counts survive the export. These are synthetic amounts, already calculated for this exercise; use explicit rules for missing inputs in a real report.
sales = pd.DataFrame({"category": ["Office", "Books", "Office", "Stationery"],
                      "revenue": [300, 400, 250, 200]})
summary = sales.groupby("category", as_index=False)["revenue"].sum()
path = export_dir / "sales_report.xlsx"
with pd.ExcelWriter(path, engine="openpyxl") as writer:
    sales.to_excel(writer, sheet_name="Details", index=False, freeze_panes=(1, 0))
    summary.to_excel(writer, sheet_name="Summary", index=False)
details_back = pd.read_excel(path, sheet_name="Details", engine="openpyxl")
summary_back = pd.read_excel(path, sheet_name="Summary", engine="openpyxl")
print(summary_back)
assert len(details_back) == 4
assert summary_back["revenue"].sum() == details_back["revenue"].sum() == 1150
Expected output
     category  revenue
0       Books      400
1      Office      550
2  Stationery      200
Download the Workbook from Colab
Open the Files sidebar, find pandas_excel_practice/sales_report.xlsx, and choose Download from its menu. Runtime files disappear when the runtime resets. For a notebook-triggered download, run the following cell only when ready; it is disabled by default so Run all does not launch downloads.
DOWNLOAD_REPORT = False

if DOWNLOAD_REPORT:
    from google.colab import files
    files.download(str(export_dir / "sales_report.xlsx"))
Write to Google Sheets Instead of an Excel File
Google Sheets uses a different workflow from an xlsx download. Follow the pygsheets guide and set_dataframe tutorial when you want to send a DataFrame to an authorized Google spreadsheet.
Common Export Problems
Unexpected index column: use index=False or give a meaningful index_label. Missing directory: create it first. Append not supported with XlsxWriter: use openpyxl for this workflow. Wrong starting cell: offsets are zero-based and headers occupy a row. Lost decimal precision: float_format writes rounded values; use cell number formatting for display only. Workbook already open: close it in Excel before replacing it if the file is locked. Untrusted text becomes a formula: define a literal-text export policy for user-supplied cells before writing. Large report: Excel has sheet size limits; choose CSV or another format when a workbook is unsuitable.
Exercise: Export Only Passing Scores
Select students with MATH at least 40. Export ID, NAME and MATH to a sheet named Passing with index=False and the header frozen. Read it back and verify that two rows were exported and their MATH total is 90.
Exercise Solution
Filter before exporting, then verify both the schema and a known numeric total. Inspect freeze_panes through openpyxl to confirm that the header row is frozen.
df = student_data()
selected = df.loc[df["MATH"].ge(40), ["ID", "NAME", "MATH"]]
path = export_dir / "passing.xlsx"
selected.to_excel(path, sheet_name="Passing", index=False,
                  freeze_panes=(1, 0), engine="openpyxl")
restored = pd.read_excel(path, sheet_name="Passing", engine="openpyxl")
print(restored)
assert len(restored) == 2
assert restored["MATH"].sum() == 90
wb = load_workbook(path)
assert wb["Passing"].freeze_panes == "A2"
wb.close()
Expected output
   ID  NAME  MATH
0   2  Raju    40
1   3  Alex    50
Review Questions
Can you explain when an index belongs in an export, why header aliases do not rename source columns, and how appending a sheet differs from appending rows? Try answering before returning to the examples.
- How do you export a Pandas DataFrame to an Excel file using the
to_excel()function? - What is the purpose of the
sheet_nameparameter in theto_excel()function? - Can you specify a custom name for the Excel file when using the
to_excel()function? - How can you exclude the index column from the exported Excel file using the
to_excel()function? - What additional optional parameters are available in the
to_excel()function to customize the Excel export? - How can you export only specific columns from a DataFrame to an Excel file using the
to_excel()function? - Is it possible to overwrite an existing Excel file when using the
to_excel()function? - How do you handle missing or empty values in the DataFrame while exporting to an Excel file?
- Can you export multiple DataFrames to separate sheets within the same Excel file using the
to_excel()function? - What file format does the
to_excel()function support for exporting DataFrames?
Practice in Google Colab
Open in Google Colab View on GitHub
Run the examples, inspect the generated workbooks and download the sales report. All synthetic sample data is embedded. See the Colab guide for file handling.
Continue with Pandas Input and Output, read_excel(), to_csv(), to_sql() and to_string(). Reference: Pandas to_excel documentation.

Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials