Pandas fillna(): Handle Missing Values Without Losing Meaning
fillna() replaces missing values with a chosen value or with different values for different columns. Start by identifying what is missing and deciding which replacements make sense. An unknown price is not automatically zero.
For example, use df.fillna({"category": "Unknown", "discount": 0}) when those rules fit your data. Unspecified columns keep their missing values. The examples below explain the choices and show their outputs.
fillna(value) for explicit replacements, ffill() for the previous observation and bfill() for the next observation. Older tutorials and the video may show fillna(method=...); use the separate methods with current Pandas.Video: Missing-Value Handling
This video demonstrates the concepts using an earlier Pandas API. When it uses fillna(method="ffill") or fillna(method="bfill"), use ffill() or bfill() as shown in this lesson.
Syntax and Parameters
DataFrame.fillna(value, *, axis=None, inplace=False, limit=None)| Parameter | Meaning |
|---|---|
value | A scalar, dictionary, Series or DataFrame. A dictionary can supply a different replacement for each column. |
axis | For a DataFrame, 0 means the index axis and 1 means columns. Direction matters for propagation and replacement limits. |
inplace | False by default: return a filled object. True: modify the object and return None. |
limit | Maximum constant-fill replacements along the chosen axis. Must be positive when specified. |
These examples were executed locally with Pandas 3.0.1. Your Colab environment may show slightly different formatting. Run print(pd.__version__) to check it.
Identify Missing Values
Both None and numeric missing values are detected by isna(). An empty string is not automatically a missing value.
import pandas as pd

df = pd.DataFrame({
    "product": ["Notebook", None, "Pen", ""],
    "quantity": [2.0, None, 4.0, 1.0],
})
print(df.to_string(index=False))
print("\nMissing values per column:")
print(df.isna().sum().to_string())
Expected output
 product  quantity
Notebook       2.0
     NaN       NaN
     Pen       4.0
               1.0

Missing values per column:
product     1
quantity    1
The empty product string is not counted. If blank strings mean missing in your dataset, normalise them before filling.
Try It Yourself
Replace the empty string with None and compare the missing-value count.
Fill a Text Column
Use an explicit string dtype and fill an unknown category with a meaningful label.
import pandas as pd

products = pd.Series(["Notebook", None, "Pen"], dtype="string")
filled = products.fillna("Unknown")
print(filled.tolist())
print("Original missing count:", int(products.isna().sum()))
Expected output
['Notebook', 'Unknown', 'Pen']
Original missing count: 1
The original Series is unchanged. A label such as "Unknown" preserves the distinction between a known and unknown product.
Fill Numeric Values When Zero Is Meaningful
In this example, a missing discount means no discount under the stated business rule. That does not imply every missing numeric value should become zero.
import pandas as pd

discount = pd.Series([5.0, None, 0.0, 10.0])
print(discount.fillna(0).tolist())
Expected output
[5.0, 0.0, 0.0, 10.0]A missing quantity or price could mean unknown information. Do not automatically apply the discount rule to those columns.
Apply Different Rules to Different Columns
A dictionary maps column names to their replacement values. Unspecified columns keep their missing values.
import pandas as pd

df = pd.DataFrame({
    "category": pd.Series(["Stationery", None, "Stationery"], dtype="string"),
    "discount": [5.0, None, 0.0],
    "unit_price": [20.0, None, 10.0],
})
cleaned = df.fillna({"category": "Unknown", "discount": 0})
print(cleaned.to_string(index=False))
assert cleaned["unit_price"].isna().sum() == 1
Expected output
  category  discount  unit_price
Stationery       5.0        20.0
   Unknown       0.0         NaN
Stationery       0.0        10.0
The unknown price remains missing. Filling numeric columns with text such as "D" can change their dtype or fail for typed columns; use column-appropriate replacements.
Compare Zero Filling with Median Filling
The median is one possible estimate, not a recovered observation. Compare how two choices change the average.
import pandas as pd

scores = pd.Series([10.0, 20.0, None, 30.0])
zero_filled = scores.fillna(0)
median_filled = scores.fillna(scores.median())
print("Observed-value mean:", scores.mean())
print("Mean after zero fill:", zero_filled.mean())
print("Mean after median fill:", median_filled.mean())
print("Median-filled values:", median_filled.tolist())
Expected output
Observed-value mean: 20.0
Mean after zero fill: 15.0
Mean after median fill: 20.0
Median-filled values: [10.0, 20.0, 20.0, 30.0]
Pandas excludes missing values from these mean and median calculations. Median filling can distort the distribution. An all-missing column has no observed median, so this strategy cannot fill it.
Try It Yourself
Change 30.0 to 300.0 and compare the results. Which assumptions justify filling?
Forward Fill Ordered Observations
Here a missing sensor reading means no new reading arrived. Use the previous observation only if that assumption fits the task. Sort timestamps before filling.
import pandas as pd

readings = pd.Series(
    [None, 20.0, None, None, 23.0],
    index=pd.date_range("2026-01-01", periods=5, freq="D"),
    name="temperature",
)
print(readings.ffill().to_string())
Expected output
2026-01-01     NaN
2026-01-02    20.0
2026-01-03    20.0
2026-01-04    20.0
2026-01-05    23.0
Freq: D
The first value stays missing because no earlier observation exists. Do not carry values across unrelated devices or customers; fill within each group when appropriate.
Backward Fill and Its Limitation
Backward fill uses the next observed value. It can be useful for a retrospective task but can introduce future information into a prediction.
import pandas as pd

readings = pd.Series([None, 20.0, None, 23.0, None])
print(readings.bfill().tolist())
Expected output
[20.0, 20.0, 23.0, 23.0, nan]The final value stays missing. Avoid backward filling when future observations would not have been available at prediction time.
Limit Replacements
fillna(value, limit=...) limits the total replacements in a Series. ffill(limit=...) limits each consecutive missing run.
import pandas as pd

values = pd.Series([1.0, None, None, 4.0, None])
print("Constant fill, limit 1:", values.fillna(0, limit=1).tolist())
print("Forward fill, limit 1:", values.ffill(limit=1).tolist())
Expected output
Constant fill, limit 1: [1.0, 0.0, nan, 4.0, nan]
Forward fill, limit 1: [1.0, 1.0, nan, 4.0, 4.0]
The two limits have different meanings. For a DataFrame, constant-fill limits apply along the selected axis.
Fill by Matching Index Labels
A replacement Series aligns by index label, not by its physical order.
import pandas as pd

prices = pd.Series([None, 15.0, None], index=["A", "B", "C"])
defaults = pd.Series([30.0, 10.0], index=["C", "A"])
print(prices.fillna(defaults).to_string())
Expected output
A    10.0
B    15.0
C    30.0
Use this when reliable replacement values are available for particular records.
Preserve the Original and Understand inplace
Assignment makes the result explicit. With inplace=True, the object is modified and the method returns None.
import pandas as pd

original = pd.DataFrame({"discount": [5.0, None, 0.0]})
cleaned = original.fillna({"discount": 0})
print("Original missing count:", int(original["discount"].isna().sum()))
print("Cleaned missing count:", int(cleaned["discount"].isna().sum()))

working = original.copy()
returned = working.fillna({"discount": 0}, inplace=True)
print("Return value with inplace=True:", returned)
print("Working values:", working["discount"].tolist())
Expected output
Original missing count: 1
Cleaned missing count: 0
Return value with inplace=True:    discount
0       5.0
1       0.0
2       0.0
Working values: [5.0, 0.0, 0.0]
Do not write df = df.fillna(..., inplace=True); it assigns None to df. For a single column, prefer df["column"] = df["column"].fillna(value) over chained inplace operations.
Practical Example: Load a Sample Sales CSV
This synthetic CSV contains five orders. It is downloaded automatically from Plus2Net in the next example. No manual upload is required in Colab.
Download the sample sales CSV using the links at the end of this page.
The file is downloaded once per run of the loading cell. Later examples reload that local file to start with fresh data. If the download fails, check your connection and rerun the cell; if the file cannot be reached, do not continue with the sales examples.
Rules for this exercise:
- A blank category means "Unknown".
- A blank discount means zero discount; the discount is a total amount per order.
- A blank quantity or price remains unknown. Do not invent an order value.
- Keep all records and flag orders whose net amount cannot be calculated.
In real data, confirm these rules with the data owner first.
import pandas as pd

from pathlib import Path
from urllib.request import urlopen

DATA_URL = "https://www.plus2net.com/python/download/pandas_fillna_sample_sales.csv"
DATA_FILE = Path("pandas_fillna_sample_sales.csv")

# Download first, then save only after a successful response.
with urlopen(DATA_URL, timeout=30) as response:
    csv_bytes = response.read()
DATA_FILE.write_bytes(csv_bytes)

def load_sales():
    data = pd.read_csv(DATA_FILE, dtype={"category": "string"})
    expected_columns = ["order_id", "category", "quantity", "unit_price", "discount"]
    if data.columns.tolist() != expected_columns:
        raise ValueError("The CSV columns do not match this lesson's sample dataset.")
    if len(data) != 5:
        raise ValueError("This lesson expects the five-order sample CSV.")
    return data

sales = load_sales()
print(sales.to_string(index=False))
Expected output
 order_id   category  quantity  unit_price  discount
     1001 Stationery       2.0        20.0       0.0
     1002       <NA>       1.0        15.0       NaN
     1003 Stationery       NaN        10.0       0.0
     1004     Office       3.0         NaN       5.0
     1005     Office       2.0        30.0       NaN
Clean, Calculate and Verify
Apply only the agreed rules. Use fresh data and verify the outcome.
import pandas as pd

sales = load_sales()
cleaned_sales = sales.fillna({"category": "Unknown", "discount": 0})
cleaned_sales["net_amount"] = (
    cleaned_sales["quantity"] * cleaned_sales["unit_price"]
    - cleaned_sales["discount"]
)
cleaned_sales["needs_review"] = cleaned_sales["net_amount"].isna()
print(cleaned_sales.to_string(index=False))
print("\nTotal for calculable orders:", cleaned_sales["net_amount"].sum(min_count=1))
print("Orders needing review:", int(cleaned_sales["needs_review"].sum()))

assert len(cleaned_sales) == len(sales)
assert cleaned_sales["order_id"].equals(sales["order_id"])
assert cleaned_sales["category"].isna().sum() == 0
assert cleaned_sales["discount"].isna().sum() == 0
assert cleaned_sales["quantity"].isna().sum() == 1
assert cleaned_sales["unit_price"].isna().sum() == 1
assert cleaned_sales["needs_review"].sum() == 2
assert pd.api.types.is_numeric_dtype(cleaned_sales["quantity"])
assert pd.api.types.is_numeric_dtype(cleaned_sales["unit_price"])
print("Verification passed.")
Expected output
 order_id   category  quantity  unit_price  discount  net_amount  needs_review
     1001 Stationery       2.0        20.0       0.0        40.0         False
     1002    Unknown       1.0        15.0       0.0        15.0         False
     1003 Stationery       NaN        10.0       0.0         NaN          True
     1004     Office       3.0         NaN       5.0         NaN          True
     1005     Office       2.0        30.0       0.0        60.0         False

Total for calculable orders: 115.0
Orders needing review: 2
Verification passed.
The total is for calculable orders only; it is not the complete sales total. Keeping the two incomplete orders visible avoids silently hiding missing information.
Fill Down Columns or Across Rows
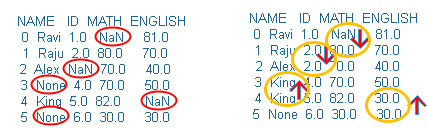
ffill(axis=0) carries values down columns; ffill(axis=1) carries values across a row. Only fill across columns when their values have compatible meanings and units.
import pandas as pd

df = pd.DataFrame({"first": [1.0, None], "second": [None, 5.0], "third": [3.0, None]})
print("Down each column:")
print(df.ffill(axis=0).to_string(index=False))
print("\nAcross each row:")
print(df.ffill(axis=1).to_string(index=False))
Expected output
Down each column:
 first  second  third
   1.0     NaN    3.0
   1.0     5.0    3.0

Across each row:
 first  second  third
   1.0     1.0    3.0
   NaN     5.0    5.0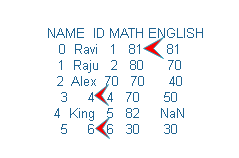
Common Mistakes and Practical Decisions
- Do not fill identifiers by carrying the previous ID forward: that can assign the wrong identity.
- Do not replace all missing numeric entries with text; preserve numeric types for calculations.
- Do not treat empty strings as missing without checking your data and normalising them.
- Do not confuse the total replacement limit in fillna with the consecutive-run limit in ffill or bfill.
- Do not use future values for a prediction task when they would not yet be available.
- Keep a record of estimated values and check missing counts, row counts and data types afterwards.
Use isnull() to identify missing values, consider dropna() when removing incomplete records is justified, and compare results using describe(). Removing or filling values is a decision about the data, not merely a syntax choice.
Practice Pandas fillna() in Google Colab
Run these examples, predict their outputs and change the cleaning rules in the sample sales exercise. No local Python installation is required.
Sign in, choose File → Save a copy in Drive, and run the setup cell first. The notebook downloads the sales CSV from Plus2Net. It includes a practice area and suggested solution.
Open in Google Colab View on GitHub Download sample sales CSVTry It Yourself
- Count missing values by column.
- Fill categories and discounts using explicit rules.
- Keep unknown quantities and prices missing.
- Flag incomplete orders and verify that no records were removed.
- Explain why the calculable-order total is not the complete sales total.
Summary and Next Steps
Identify missing values, choose replacements by column, and verify their consequences. Keep unknown values when filling would invent information. Continue with Pandas data cleaning or summary statistics with describe().
References: Pandas fillna, ffill and bfill.
Pandas Tutorials Pandas DataFrame
Subhendu Mohapatra
Author & Instructor at plus2net
I write and maintain practical tutorials on Python, PHP, SQL, JavaScript, HTML, jQuery, and web development at plus2net. The tutorials focus on clear explanations, working examples, and code that readers can test and adapt while learning.


Subscribe to our YouTube Channel here

 Python Video Tutorials